En bref
Un chapitre d’un livre japonais de programmation, aux phrases pleines de mots anglais, de code et de nombres. Postext règle la ponctuation et les fins de ligne à la japonaise et ajoute une espace fine entre japonais et latin.
Ce que vous allez composer
Cinq pages du chapitre 3 d’un livre japonais de programmation imaginaire, 実践 日本語テキスト処理 (Traitement pratique du texte japonais), consacré à la normalisation Unicode. Il est composé comme les livres d’informatique japonais : format A5, une colonne de 36 caractères sur 29 lignes de Noto Serif JP en 9 pt, titres en Noto Sans JP, code en BIZ UDGothic. Ce texte est le cas difficile de la composition japonaise, car une phrase sur deux contient un mot latin, un point de code, un nombre ou un nom de fonction : les fins de ligne suivent le 禁則処理 (kinsoku shori) le plus strict de JLReq, la ponctuation garde son espacement pleine chasse, et un quart de cadratin sépare le japonais du latin sans que personne tape d’espace. Une figure, un tableau, un listing et des notes de bas de page portent des étiquettes japonaises : 図3-1, 表3-1, des numéros de note en exposant comptés par page. Listings de code et touches de clavier est le même genre de page, en anglais.
Cette recette répond à
- Comment espacer la ponctuation japonaise : 、。「」 resserrés là où ils se rencontrent, une espace après ?! et le crochet qui ouvre un paragraphe ?
- Pourquoi les petits kana, ー et les crochets fermants ne peuvent-ils pas commencer une ligne en japonais, et comment choisir la sévérité de la règle ?
- Pourquoi mon texte japonais sort-il avec les règles chinoises : étiquettes 图, petits kana en début de ligne, kanji sous leurs formes chinoises ?
La réponse courte
// locale 'ja' turns on JLReq composition: kinsoku at its strictest, full-width marks squeezed
// where two meet (」、 takes one em, not two), a closing mark keeps its half em at a line
// end, 、。 may hang past it, and a paragraph opening with 「 sets the bracket in the indent.
// The values below are the ones 'auto' picks for 'ja'; they are spelled out to be seen.
const cjk = {
  lineBreak: 'ja-very-strict', // no line starts with ー, small kana, 々, 」、。?・ or :
  punctuationWidth: 'fullwidth', // 、。「」 keep their em inside the line (JLReq §3.1.2)
  hangingPunctuation: 'allow', // 、。 hang only when the line would otherwise break before them
  paragraphStartBracket: 'half', // 「 at a paragraph start sits in the indent's second half
  latinSpacing: em(0.25), // 四分アキ between kana or kanji and Latin letters or digits
  grid: { enabled: true, charsPerLine: CHARS, linesPerPage: LINES }, // whole ems, whole lines
};
// The Latin is the Japanese face's own proportional Latin, at the text's size: never
// full-width A or a second face for the words in parentheses.
const bodyText = {
  fontFamily: MINCHO, fontSize: pt(BODY), lineHeight: pt(PITCH), color: col('ink'),
  boldColor: col('ink'), italicColor: col('ink'), referenceColor: col('ink'),
  textAlign: 'justify', firstLineIndent: em(1), indentAfterHeading: true, // 1 字下げ
  referenceBold: false, // 図3-1 and 表3-1 in the text weight: the face loads no bold
  hyphenation: { enabled: false }, avoidRunts: true, // no one-character last line
  // The grid cuts a list where the page ends: the four forms stay in one piece.
  shortListSplit: 'avoid', shortListMaxItems: 4,
};
Ingrédients
- Fonctionnalités
- Espacement de la ponctuation japonaise (yakumono)Coupure des lignes en japonais (kinsoku)Espace entre chinois et latinNotes dans les livres japonaisNotes de bas de pageLégendes numérotéesFigure et Tableau dans votre langueTitres numérotésTitres sur plusieurs lignes du texte (gyōdori)Grille de caractèresPolices chinoises, japonaises et coréennesListings de codeEncadrésStyle de tableauStyle des légendesFigures et tableaux comme ressourcesTitres courants et foliosOuvertures composéesPalette de couleurs sémantiqueExport PDF
- Utilise aussi
- Citations dans un style bibliographiqueCoupure des lignes en chinoisLargeur de la ponctuation chinoiseÉquilibrage des colonnesRenvoisDes figures exactement iciTitres courants selon le rôle de la pageStyles de paragraphePolices intégrées au PDFTypes de ressource personnalisésTableaux à partir de données
- Typographie
- Noto Serif JP, Noto Sans JP, BIZ UDGothic (SIL OFL 1.1)
- Ressources
- Figure 3-1, the bytes of が, drawn in code in the page’s palette (Postext Cookbook, CC BY 4.0)
Préparation
#1 · Les règles japonaises viennent avec la balise de langue
Le code est dans la réponse courte plus haut. locale: 'ja' active les règles de JLReq, les Requirements for Japanese Text Layout du W3C, et les valeurs écrites sous cjk sont celles que 'auto' choisit pour le japonais (Typographie d’Asie orientale). Au niveau ja-very-strict, aucune ligne ne commence par ー, un petit kana, 々 ou un signe fermant, et aucune ne finit sur un crochet ouvrant. La ponctuation (約物, yakumono) garde son cadratin entier dans la ligne, et deux signes qui se rencontrent, comme 」、, se partagent un cadratin. Sur la page 41, la ligne qui finit sur 実際に変換し、 place son 、 au-delà du bord droit de la justification : c’est le ぶら下げ (burasage), et le moteur n’y recourt que si la ligne devait sinon renvoyer le signe à la ligne suivante. latinSpacing met un quart de cadratin (四分アキ, shibun aki) entre Unicode et では, et entre U+304C et を, bien que le Markdown n’ait là aucune espace. Il ne s’applique qu’à côté d’une lettre ou d’un chiffre : normalize() et is_normalized() se terminent par une parenthèse, si bien que le Markdown tape une espace entre elles et 関数.
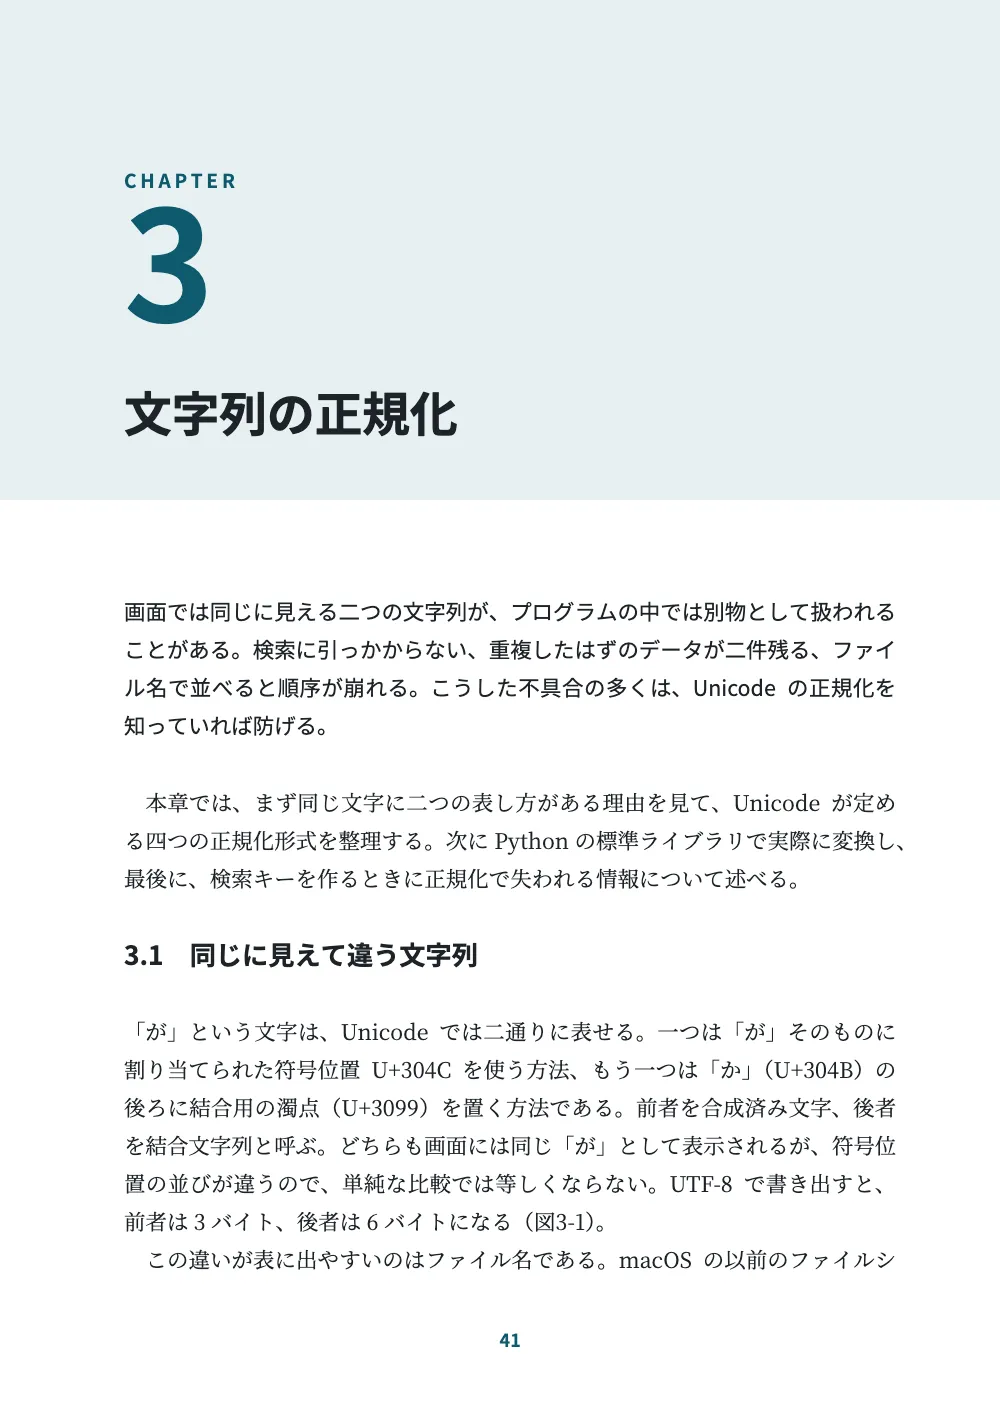
La différence avec le chinois tient aux signes. Un livre de Chine continentale compose par défaut 、 et , en demi-chasse et 。 en pleine chasse (Kaiming) ; un livre japonais garde tous les signes en pleine chasse et ne les resserre que là où deux se rencontrent. La coupure des lignes en chinois n’a ni petits kana ni ー à tenir loin d’un début de ligne : ja-very-strict est donc un niveau à part.
#2 · Le code dans un caractère à chasse fixe qui a des kana
// A ``` fence is set line by line as written, in codeStyle's face: the monospaced face,
// which has kana and kanji too, so a full-width character takes two half-width cells.
// The rest of the fence line (normalize.py) is the listing's title. Inline `code` is set
// in the same face, in the accent.
const codeStyle = {
  fontFamily: CODE, fontSize: pt(8), lineHeight: pt(12), color: col('ink'),
  background: col('tint'), snapToGrid: false, highlight: 'none', // one ink, as in print
  padding: { top: mm(2.5), right: mm(4), bottom: mm(3), left: mm(4) },
  marginTop: mm(2), marginBottom: mm(2),
  titleStyle: { fontFamily: CODE, fontSize: pt(7), fontWeight: 400, color: col('teal') },
  inline: { fontSize: pt(8.5), color: col('teal') },
};
Le bloc délimité est un bloc de code : Postext compose ses lignes telles qu’elles sont tapées, dans le caractère que nomme codeStyle, dans une boîte teintée sous le titre normalize.py repris de la ligne d’ouverture (listings de code). highlight: 'none' garde le listing d’une seule encre, comme le reste de la page, et codeStyle.inline compose chaque `name` dans le même caractère, en sarcelle. Le choix du caractère compte : la chaîne de l’exemple, ガイド ABC ①, demande des katakana demi-chasse, des lettres pleine chasse et des chiffres cerclés, qui manquent à un caractère de code occidental. BIZ UDGothic compose le latin demi-chasse et les kana pleine chasse à pas fixe, et un listing compte un caractère pleine chasse pour deux cellules : les colonnes restent alignées.
#3 · 図3-1 et 表3-1
const FORMS = `入力\tNFC\tNFD\tNFKC
が(U+304C)\tU+304C\tU+304B U+3099\tU+304C
ガ(U+FF76 U+FF9E)\tそのまま\tそのまま\tガ(U+30AC)
ABC(全角)\tそのまま\tそのまま\tABC
①\tそのまま\tそのまま\t1
㍻\tそのまま\tそのまま\t平成`;
const resources = [
  { id: 'tbl:forms', typeId: 'table', kind: 'table', createdAt: 0, updatedAt: 0,
    placement: { position: 'here' }, // at its ::resource line, under the paragraph citing it
    caption: '日本語の文字と四つの正規化形式(NFKDは、NFKCで合成された文字を分解した形になる)',
    table: { model: { ...parseTSV(FORMS), headerRowCount: 1, columnWidths: [34, 18, 26, 22] } } },
  { id: 'fig:bytes', typeId: 'figure', kind: 'svg', createdAt: 0, updatedAt: 0,
    caption: '「が」の二つの表し方。上段が符号位置、下段がUTF-8のバイト列',
    altText: 'が as one code point U+304C, three UTF-8 bytes E3 81 8C; and as U+304B and the '
      + 'combining voiced mark U+3099, six bytes E3 81 8B E3 82 99.',
    svg: { fileId: 'bytes.svg', width: 1175, height: 400 } },
];
defaultResourceTypes('ja') nomme les types 図 et 表 et les numérote par chapitre avec un trait d’union, et continuation.headings fait de ce chapitre le chapitre 3 : la première figure est donc 図3-1. Un document ja compose l’étiquette et le numéro sans espace et place une espace idéographique après le numéro, comme les livres japonais impriment 図3-1 「が」の二つの表し方 ; le style de légende ne choisit donc que le caractère et les couleurs. Le tableau est placé 'here', sous le paragraphe qui le cite. Les étiquettes de la figure sont uniquement latines, U+304C et E3 81 8C : le SVG nomme le caractère de code dans son style, et loadSvg intègre le fichier de police avant que l’image soit dessinée.
#4 · Des notes par page, à la japonaise
  footnotes: { fontSize: pt(7.5), lineHeight: pt(12), color: col('ink'),
    separator: { color: col('rule') } }, // at the column foot, 1 on each page, superscript
Les notes n’ont besoin d’aucun réglage en dehors de leur corps : dans un document japonais horizontal, les valeurs par défaut sont celles que JLReq décrit pour les livres horizontaux, une note au pied de la colonne où elle est appelée, numérotée à partir de 1 à chaque page, un appel en exposant et un filet long d’un tiers de la justification (Notes de bas de page). L’appel se place avant le point, 保存していた[^hfs]。, si bien que le 。 ne commence jamais la ligne suivante séparé de lui.
#5 · Un titre de section sur trois lignes
const BAND = 74; // mm from the trim's top
const opener = { enabled: true, minHeight: pt(PITCH * 10), slot: { elements: [ // text: line 11
  { kind: 'box', id: 'band', reserve: false, style: { backgroundColor: col('tint') },
    placement: { anchor: { to: 'page', edge: 'top-left' },
      size: { width: 'fill', height: mm(BAND) } } },
  { kind: 'text', id: 'kicker', content: 'CHAPTER', fontFamily: GOTHIC, fontSize: pt(8),
    fontWeight: 700, letterSpacing: pt(1.6), color: col('teal'), align: 'left',
    placement: { anchor: { to: 'container', edge: 'top-left' }, offset: { y: mm(0) } } },
  { kind: 'text', id: 'number', content: '{numberDecimal}', fontFamily: GOTHIC, fontSize: pt(64),
    lineHeight: 1, fontWeight: 700, color: col('teal'), align: 'left',
    placement: { anchor: { to: '#kicker', edge: 'below' }, offset: { y: mm(1) } } },
  { kind: 'text', id: 'title', content: '{titleText}', fontFamily: GOTHIC,
    fontSize: pt(20), fontWeight: 700, color: col('ink'), align: 'left', overflow: 'wrap',
    placement: { anchor: { to: '#number', edge: 'below' }, offset: { y: mm(5) },
      size: { width: mm(MEASURE) } } },
] } };
L’ouverture de chapitre est une maquette posée sur le H1 : une bande sarcelle, le numéro du chapitre en 64 pt tiré de {numberDecimal} et le titre. Les titres de section utilisent lineSpan: 3, le 行取り (gyōdori) : chacun occupe exactement trois lignes du texte courant, son texte centré dedans, et le texte qui suit continue au pas de la grille. headings.balancing.enabled: false empêche le moteur d’ajouter des lignes au-dessus des titres pour équilibrer une page.
La recette complète
// ═══ Postext Cookbook · Nº 123 · A Japanese technical manual: kana, kanji and Latin ═══ // https://postext.dev/en/cookbook/japanese-technical-manual // Code: MIT · Text: original (CC BY 4.0) · Pictures: drawn in code // Fonts: Noto Serif JP, Noto Sans JP, BIZ UDGothic (SIL OFL 1.1) · Needs postext ≥ 1.28.0 import { buildDocument, withLoadedFonts, renderPageToCanvas, defaultResourceTypes, parseTSV, registerResourceImage, inlineSvgFonts, } from 'https://esm.sh/postext'; import { renderToPdf, decompressWoff2 } from 'https://esm.sh/postext-pdf'; const LANG = 'en'; // @lang: the language of the frame; the chapter is Japanese in both const RECIPE = 'japanese-technical-manual'; // ─── 1 · Design ───────────────────────────────────────────────────────────── // #region palette: ink, one deep teal for numbers, rules and labels, a pale tint for code const palette = { ink: '#1d2327', // text: a cool near-black teal: '#0e5a6e', // the one accent: chapter number, heads' numbers, labels, the point box tint: '#e7f0f2', // the opener band, the listing's ground rule: '#b9c6cc', // hairlines: table rules, the note rule muted: '#5b666d', // running heads, folios, colophon paper: '#ffffff', }; const col = (id) => ({ hex: palette[id], model: 'hex', paletteId: id }); const colorPalette = Object.entries({ ...palette, 'main-color': palette.teal }) .map(([id, hex]) => ({ id, name: id, value: { hex, model: 'hex' } })); // #endregion const [MINCHO, GOTHIC, CODE] = ['Noto Serif JP', 'Noto Sans JP', 'BIZ UDGothic']; const [BODY, PITCH] = [9, 16]; // pt: 9 pt text on a 16 pt line, 1.78 × the size const [CHARS, LINES] = [36, 29]; // the type area in characters: 36 to a line, 29 lines const MEASURE = CHARS * BODY * 25.4 / 72; // mm: 114.3 // #region answer: Japanese rules from the tag, written out; the quarter-em Latin space // locale 'ja' turns on JLReq composition: kinsoku at its strictest, full-width marks squeezed // where two meet (」、 takes one em, not two), a closing mark keeps its half em at a line // end, 、。 may hang past it, and a paragraph opening with 「 sets the bracket in the indent. // The values below are the ones 'auto' picks for 'ja'; they are spelled out to be seen. const cjk = { lineBreak: 'ja-very-strict', // no line starts with ー, small kana, 々, 」、。?・ or : punctuationWidth: 'fullwidth', // 、。「」 keep their em inside the line (JLReq §3.1.2) hangingPunctuation: 'allow', // 、。 hang only when the line would otherwise break before them paragraphStartBracket: 'half', // 「 at a paragraph start sits in the indent's second half latinSpacing: em(0.25), // 四分アキ between kana or kanji and Latin letters or digits grid: { enabled: true, charsPerLine: CHARS, linesPerPage: LINES }, // whole ems, whole lines }; // The Latin is the Japanese face's own proportional Latin, at the text's size: never // full-width A or a second face for the words in parentheses. const bodyText = { fontFamily: MINCHO, fontSize: pt(BODY), lineHeight: pt(PITCH), color: col('ink'), boldColor: col('ink'), italicColor: col('ink'), referenceColor: col('ink'), textAlign: 'justify', firstLineIndent: em(1), indentAfterHeading: true, // 1 字下げ referenceBold: false, // 図3-1 and 表3-1 in the text weight: the face loads no bold hyphenation: { enabled: false }, avoidRunts: true, // no one-character last line // The grid cuts a list where the page ends: the four forms stay in one piece. shortListSplit: 'avoid', shortListMaxItems: 4, }; // #endregion // #region listing: a fenced block is a code listing in a tinted box // A ``` fence is set line by line as written, in codeStyle's face: the monospaced face, // which has kana and kanji too, so a full-width character takes two half-width cells. // The rest of the fence line (normalize.py) is the listing's title. Inline `code` is set // in the same face, in the accent. const codeStyle = { fontFamily: CODE, fontSize: pt(8), lineHeight: pt(12), color: col('ink'), background: col('tint'), snapToGrid: false, highlight: 'none', // one ink, as in print padding: { top: mm(2.5), right: mm(4), bottom: mm(3), left: mm(4) }, marginTop: mm(2), marginBottom: mm(2), titleStyle: { fontFamily: CODE, fontSize: pt(7), fontWeight: 400, color: col('teal') }, inline: { fontSize: pt(8.5), color: col('teal') }, }; // #endregion // #region opener: a tinted band, the chapter number large in the accent, the title under it const BAND = 74; // mm from the trim's top const opener = { enabled: true, minHeight: pt(PITCH * 10), slot: { elements: [ // text: line 11 { kind: 'box', id: 'band', reserve: false, style: { backgroundColor: col('tint') }, placement: { anchor: { to: 'page', edge: 'top-left' }, size: { width: 'fill', height: mm(BAND) } } }, { kind: 'text', id: 'kicker', content: 'CHAPTER', fontFamily: GOTHIC, fontSize: pt(8), fontWeight: 700, letterSpacing: pt(1.6), color: col('teal'), align: 'left', placement: { anchor: { to: 'container', edge: 'top-left' }, offset: { y: mm(0) } } }, { kind: 'text', id: 'number', content: '{numberDecimal}', fontFamily: GOTHIC, fontSize: pt(64), lineHeight: 1, fontWeight: 700, color: col('teal'), align: 'left', placement: { anchor: { to: '#kicker', edge: 'below' }, offset: { y: mm(1) } } }, { kind: 'text', id: 'title', content: '{titleText}', fontFamily: GOTHIC, fontSize: pt(20), fontWeight: 700, color: col('ink'), align: 'left', overflow: 'wrap', placement: { anchor: { to: '#number', edge: 'below' }, offset: { y: mm(5) }, size: { width: mm(MEASURE) } } }, ] } }; // #endregion // Running heads: the book on the verso, the chapter on the recto, folios outside. // Anchored to the header's container, which spans the measure, so they align with the text // wherever the grid puts its margins. const head = (id, content, parity, edge, x, extra) => ({ kind: 'text', id, content, parity, pages: 'body', fontFamily: GOTHIC, fontSize: pt(7.5), color: col('muted'), align: edge.endsWith('left') ? 'left' : 'right', placement: { anchor: { to: 'container', edge }, offset: { x: mm(x), y: mm(13) } }, ...extra }); const folio = { fontWeight: 700, color: col('teal') }; const header = { elements: [ head('v-folio', '{pageNumber}', 'even', 'top-left', 0, folio), head('v-title', '{title}', 'even', 'top-left', 8), head('r-title', '{chapterNumber} {chapterTitle}', 'odd', 'top-right', -8), head('r-folio', '{pageNumber}', 'odd', 'top-right', 0, folio), ] }; const config = () => ({ locale: 'ja', // written out, never LANG (gotcha: ja-locale-tag) resourceTypes: defaultResourceTypes('ja'), // 図 and 表, numbered by chapter: 図3-1 colorPalette, page: { sizePreset: 'custom', width: mm(148), height: mm(210), dpi: 150, // A5 // Minimums: the grid grows them to centre its 36 × 29 area, the head deeper than the foot. margins: { top: mm(23), bottom: mm(19), left: mm(17), right: mm(14), mirror: true } }, layout: { layoutType: 'single' }, cjk, bodyText, headings: { fontFamily: GOTHIC, fontWeight: 700, color: col('ink'), balancing: { enabled: false }, // no lines added above heads: the grid holds levels: [ // parity 'odd': the chapter opens on a recto, after a blank verso only when one is needed. { level: 1, numberingTemplate: '第{1}章', breakBefore: { enabled: true, parity: 'odd' }, advancedDesign: opener }, // 3行取り: each section head takes three body lines, so the grid holds across it. { level: 2, numberingTemplate: '{1}.{2}', numberSeparator: ' ', fontSize: pt(11), lineSpan: 3 }, ] }, // #region notes: only their size and colour; placement and numbering are the 'ja' defaults footnotes: { fontSize: pt(7.5), lineHeight: pt(12), color: col('ink'), separator: { color: col('rule') } }, // at the column foot, 1 on each page, superscript // #endregion unorderedLists: { bulletChar: '・', color: col('teal'), fontWeight: 400, marginTop: pt(0), marginBottom: pt(0) }, codeStyle, calloutStyles: [ { id: 'point', backgroundEnabled: false, stripe: { enabled: true, side: 'left', width: pt(3), color: col('teal') }, padding: { top: mm(0), right: mm(0), bottom: mm(0), left: mm(5) }, marginTop: pt(PITCH), marginBottom: pt(PITCH), titleStyle: { fontFamily: GOTHIC, fontSize: pt(8), fontWeight: 700, color: col('teal') }, body: { fontFamily: GOTHIC, fontSize: pt(BODY), lineHeight: pt(PITCH), color: col('ink'), firstLineIndent: pt(0), textAlign: 'justify' } }, ], tableStyle: { rules: 'horizontal', borderColor: col('rule'), borderWidth: pt(0.5), headerBackground: col('teal'), headerColor: col('paper'), headerFontFamily: GOTHIC, bodyFontFamily: MINCHO, bodyFontSize: pt(8), bodyColor: col('ink'), cellPadding: mm(1.2) }, captionStyle: { fontFamily: GOTHIC, fontSize: pt(8), color: col('ink'), labelBold: true, labelColor: col('teal') }, // 図3-1 …, the ja default paragraphStyles: [ { id: 'lead', fontFamily: GOTHIC, fontSize: pt(BODY), lineHeight: pt(PITCH), color: col('ink'), firstLineIndent: pt(0), marginBottom: pt(PITCH) }, { id: 'colophon', fontFamily: GOTHIC, fontSize: pt(6.5), lineHeight: pt(9), color: col('muted'), firstLineIndent: pt(0), textAlign: 'left', marginTop: pt(PITCH) }, ], header, footer: { elements: [{ kind: 'text', id: 'drop-folio', content: '{pageNumber}', pages: 'opener', fontFamily: GOTHIC, fontSize: pt(7.5), fontWeight: 700, color: col('teal'), align: 'center', placement: { anchor: { to: 'container', edge: 'bottom' }, offset: { y: mm(-10) } } }] }, // a drop folio on the opener }); // ─── 2 · Content ──────────────────────────────────────────────────────────── const markdown = `---Exemple Markdown · 69 lignes · content.en.md
title: "実践 日本語テキスト処理" --- # 文字列の正規化 :::paragraphs{style="lead"} 画面では同じに見える二つの文字列が、プログラムの中では別物として扱われることがある。検索に引っかからない、重複したはずのデータが二件残る、ファイル名で並べると順序が崩れる。こうした不具合の多くは、Unicodeの正規化を知っていれば防げる。 ::: 本章では、まず同じ文字に二つの表し方がある理由を見て、Unicodeが定める四つの正規化形式を整理する。次にPythonの標準ライブラリで実際に変換し、最後に、検索キーを作るときに正規化で失われる情報について述べる。 ## 同じに見えて違う文字列 「が」という文字は、Unicodeでは二通りに表せる。一つは「が」そのものに割り当てられた符号位置U+304Cを使う方法、もう一つは「か」(U+304B)の後ろに結合用の濁点(U+3099)を置く方法である。前者を合成済み文字、後者を結合文字列と呼ぶ。どちらも画面には同じ「が」として表示されるが、符号位置の並びが違うので、単純な比較では等しくならない。UTF-8で書き出すと、前者は3バイト、後者は6バイトになる([@fig:bytes])。 ::resource{id="fig:bytes"} この違いが表に出やすいのはファイル名である。macOSの以前のファイルシステムHFS+は、ファイル名を分解した形で保存していた[^hfs]。Macで作った「データ.csv」をWindowsやLinuxのサーバーにコピーすると、「テ」と濁点が分かれた名前のまま届く。見た目は同じ名前のファイルが二つ並んだり、プログラムからファイルを開けなかったりするのはこのためだ。 ## 四つの正規化形式 Unicodeは、こうした表し方の違いをそろえる手順を「正規化形式」として定めている[^uax15]。正規化形式は、二つの観点の組み合わせで四つある。 一つ目の観点は、合成するか分解するかである。分解(decomposition)は「が」を「か」と濁点に分け、合成(composition)は分けたものを一文字に戻す。二つ目の観点は、どこまでを同じ文字とみなすかである。正準等価は、見た目も意味も同じものだけを同一視する。互換等価は、半角カナと全角カナ、丸数字と数字のように、形は違っても同じ文字として扱えるものまで同一視する。 - NFC:正準分解したあと、正準合成する - NFD:正準分解する - NFKC:互換分解したあと、正準合成する - NFKD:互換分解する 日本語の文字がそれぞれの形式でどう変わるかを[@tbl:forms]に示す。NFCとNFDが変えるのは濁点と半濁点の付け方だけで、文字の種類は変わらない。一方、NFKCとNFKDは、半角カナを全角に、全角英数字を半角に、「①」を「1」に、「㍻」を「平成」に置き換える。 ::resource{id="tbl:forms"} ## Pythonで正規化する Pythonでは、標準ライブラリの\`unicodedata\`モジュールにある\`normalize()\`関数で正規化できる。第1引数に形式の名前を、第2引数に文字列を渡す。 \`\`\`python normalize.py import unicodedata s = "ガイド ABC ①" for form in ("NFC", "NFKC"): print(form, unicodedata.normalize(form, s)) \`\`\` 実行すると、NFCの行には入力がそのまま出力され、NFKCの行には「ガイド ABC 1」が出力される。半角の「カ」と「゙」が、一文字の「ガ」になっている点に注意してほしい。互換分解で「ガ」が「カ」と結合用の濁点に分かれ、続く正準合成で「ガ」にまとめられるからだ。 Python 3.8で加わった\`is_normalized()\`関数を使うと、文字列がすでに正規化されているかどうかを調べられる。読み込んだデータのうち変換の要るものだけを選べるので、大量のファイル名やレコードを処理するときに役に立つ。 ## 検索キーを作るときの注意 利用者が入力した語で検索する場合、検索キーと検索対象の両方をNFKCで正規化しておけば、半角と全角の違いを気にせずに照合できる。ただし、NFKCは情報を捨てる変換でもある。「①」は「1」に、「㈱」は「(株)」になり、元の文字には戻せない。 :::callout{type="point" title="ポイント"} 正規化した文字列は、検索と照合のためだけに使う。画面に表示する文字列と保存する文字列には、利用者が入力したものをそのまま残しておく。 ::: もう一つ、NFKCでもそろわない揺れがある。波ダッシュ「〜」(U+301C)と全角チルダ「~」(U+FF5E)だ。NFKCは全角チルダを半角の「~」に変えるが、波ダッシュは変えない[^wave]。そのため「10〜20」と「10~20」は、NFKCを通しても一致しない。こうした文字は、正規化とは別に対応表を用意して置き換える必要がある。 [^hfs]: HFS+が使うのは、Unicodeの規格のNFDに近い独自の分解形である。2017年に導入されたAPFSは、ファイル名を書かれたとおりに保存する。 [^uax15]: Unicode Standard Annex #15「Unicode Normalization Forms」。Unicodeの版ごとに改訂され、unicode.orgで公開されている。 [^wave]: Shift_JISの0x8160は、JISの対応表では波ダッシュに、マイクロソフトのCP932の表では全角チルダに変換される。同じ文書でも、変換に使った表によって符号位置が分かれる。 :::paragraphs{style="colophon"} A specimen chapter written for the Postext Cookbook; the book and its other chapters are fictitious. Set in Noto Serif JP, Noto Sans JP and BIZ UDGothic (SIL OFL). Text: CC BY 4.0. :::`; // content.<lang>.md: the same Japanese chapter in both // #region resources: the table of forms, and the bytes of が drawn in code const FORMS = `入力\tNFC\tNFD\tNFKC が(U+304C)\tU+304C\tU+304B U+3099\tU+304C ガ(U+FF76 U+FF9E)\tそのまま\tそのまま\tガ(U+30AC) ABC(全角)\tそのまま\tそのまま\tABC ①\tそのまま\tそのまま\t1 ㍻\tそのまま\tそのまま\t平成`; const resources = [ { id: 'tbl:forms', typeId: 'table', kind: 'table', createdAt: 0, updatedAt: 0, placement: { position: 'here' }, // at its ::resource line, under the paragraph citing it caption: '日本語の文字と四つの正規化形式(NFKDは、NFKCで合成された文字を分解した形になる)', table: { model: { ...parseTSV(FORMS), headerRowCount: 1, columnWidths: [34, 18, 26, 22] } } }, { id: 'fig:bytes', typeId: 'figure', kind: 'svg', createdAt: 0, updatedAt: 0, caption: '「が」の二つの表し方。上段が符号位置、下段がUTF-8のバイト列', altText: 'が as one code point U+304C, three UTF-8 bytes E3 81 8C; and as U+304B and the ' + 'combining voiced mark U+3099, six bytes E3 81 8B E3 82 99.', svg: { fileId: 'bytes.svg', width: 1175, height: 400 } }, ]; // #endregion // #region art: the figure's labels name the code face, and loadSvg embeds its file const LABELS = `text{font-family:"${CODE}";font-size:3.2px;text-anchor:middle;fill:${palette.ink}}`; function bytesArt() { const box = (x, y, w, h, fill, stroke, text) => `<rect x="${x}" y="${y}" width="${w}" ` + `height="${h}" fill="${palette[fill]}" stroke="${palette[stroke]}" stroke-width=".3"/>` + `<text x="${x + w / 2}" y="${y + h / 2 + 1.1}">${text}</text>`; const side = (x, y, text, color) => `<text x="${x}" y="${y}" style="fill:${palette[color]};` + `font-size:3.6px">${text}</text>`; const row = (y, label, points, bytes) => side(14, y + 9, label, 'teal') + points.map((p, i) => box(26 + i * 31, y, 30, 7, 'tint', 'teal', p)).join('') + bytes.map((b, i) => box(26 + i * 10 + Math.floor(i / 3), y + 9, 9.5, 7, 'paper', 'rule', b)) .join('') + side(103, y + 9, `${bytes.length} bytes`, 'muted'); return `<svg xmlns="http://www.w3.org/2000/svg" width="1175" height="400" viewBox="0 0 117.5 40">` + `<style>${LABELS}</style>${row(3, 'NFC', ['U+304C'], ['E3', '81', '8C'])}` + `${row(22, 'NFD', ['U+304B', 'U+3099'], ['E3', '81', '8B', 'E3', '82', '99'])}</svg>`; } // #endregion // ─── 3 · Fonts ────────────────────────────────────────────────────────────── const FONTS = { // every face the pages use, loaded before the build 'Noto Serif JP': ['400'], // 明朝: the text, the notes, the table 'Noto Sans JP': ['400', '700'], // ゴシック: heads, the lead, labels, the point box, folios 'BIZ UDGothic': ['400'], // the code: fixed pitch, half-width Latin, inline and in the listing }; // ─── 4 · Build & show ─────────────────────────────────────────────────────── // Each Japanese face loads the files of what it sets (gotcha: cjk-fonts-slices). const all = (re) => (markdown.match(re) ?? []).join(''); const gothic = `${all(/^#+ .*$/gm)}${all(/:::paragraphs\{style="lead"\}\n[^\n]*/g)}` + `${all(/:::callout\{type="point"[\s\S]*?\n:::/g)}${resources.map((r) => r.caption).join('')}` + '入力NFCDK第章実践日本語テキスト処理CHAPTER0123456789'; await loadFonts(FONTS, markdown); await loadCjkFonts({ [MINCHO]: FONTS[MINCHO] }, `${markdown}${FORMS}`); await loadCjkFonts({ [GOTHIC]: FONTS[GOTHIC] }, gothic); const code = (markdown.match(/^```[\s\S]*?^```$|`[^`\n]+`/gm) ?? []).join(''); await loadCjkFonts({ [CODE]: FONTS[CODE] }, code); await loadSvg('bytes.svg', bytesArt()); const continuation = { pageIndexOffset: 40, pageNumbering: { startAt: 41 }, headings: { h1: 2 } }; const doc = await withLoadedFonts(() => buildDocument({ markdown, resources, continuation }, config()), { ...kitFonts(FONTS), text: markdown }); showPages(doc, { title: t({ en: 'A Japanese technical manual', es: 'Un manual técnico japonés' }) }); offerPdf(() => renderToPdf(doc, { fontProvider: cjkPdfProvider, resourceBytes: imageBytes }), `${RECIPE}.pdf`);Kit · core, fonts, viewer, pdf, images, cjk : identique dans toutes les recettes · 504 lignes
// ─── Kit ── helpers shared by every Cookbook recipe · postext.dev/cookbook ───── // ─── Kit · core v1 ── the same in every recipe · postext.dev/cookbook function mm(value) { return { value, unit: 'mm' }; } function pt(value) { return { value, unit: 'pt' }; } function em(value) { return { value, unit: 'em' }; } /** The sample language's string: t({ en: 'Figure', es: 'Figura' }). */ function t(strings) { return strings[LANG] ?? Object.values(strings)[0]; } /** A file in this recipe's assets folder, served from the Postext repo by jsDelivr. */ function asset(file) { return `https://cdn.jsdelivr.net/gh/drnachio/postext@main/cookbook/${RECIPE}/assets/${file}`; } // ─── Kit · fonts v3 ── the same in every recipe · postext.dev/cookbook // Postext loads the faces a config asks for before layout (prepareFonts, // buildDocumentWithFonts) and asks the kit for the files: Fontsource's, the // files the PDF embeds too. /** The options of buildDocumentWithFonts / prepareFonts / withLoadedFonts: * the Fontsource resolver, and the faces of FONTS loaded with the ones the * config names. FONTS = { 'Family Name': ['400', '400i', '700'] }. */ function kitFonts(FONTS = {}) { const faces = Object.entries(FONTS).flatMap(([family, specs]) => specs.map((spec) => ({ family, weight: parseInt(spec, 10), style: spec.endsWith('i') ? 'italic' : 'normal' }))); return { resolve: fontsourceResolver, faces }; } /** A face's Fontsource files, in a fixed order: latin, then latin-ext and greek * when `text` needs them and the family ships them (kitSubsetsFor), each with * its unicode-range. Null for a weight or slant Fontsource does not ship. */ async function fontsourceResolver(family, weight, style, { text = '' } = {}) { const id = fontsourceId(family); const meta = await fontsourceMeta(family); if (meta && !(meta.weights.includes(weight) && meta.styles.includes(style))) return null; kitStatus('Loading fonts…'); const at = await fontsourceAt(id); return ['latin', ...kitSubsetsFor(text, meta)].map((subset) => ({ source: `${at}files/${id}-${subset}-${weight}-${style}.woff2`, unicodeRange: kitRanges()[subset], })); } /** The unicode-range of each Fontsource file the kit loads (a function: the * kit is inlined after the pen's code, which runs before a const would be set). */ function kitRanges() { return { latin: 'U+0000-00FF,U+0131,U+0152-0153,U+02BB-02BC,U+02C6,U+02DA,U+02DC,U+0304,U+0308,U+0329,' + 'U+2000-206F,U+20AC,U+2122,U+2191,U+2193,U+2212,U+2215,U+FEFF,U+FFFD', 'latin-ext': 'U+0100-02BA,U+02BD-02C5,U+02C7-02CC,U+02CE-02D7,U+02DD-02FF,U+0304,U+0308,U+0329,' + 'U+1D00-1DBF,U+1E00-1E9F,U+1EF2-1EFF,U+2020,U+20A0-20AB,U+20AD-20C0,U+2113,U+2C60-2C7F,U+A720-A7FF', greek: 'U+0370-03FF', }; } /** For the cjk, arabic and comics blocks, which add their own files: the * faces of `faces` = { 'Family Name': ['400', '400i', '700'] }. `text` is the sample: * č ł † α χ also load latin-ext and greek files (kitSubsetsFor). With * `optional`, a face Fontsource does not ship is skipped instead of failing. * The files are added once all have loaded, in the order asked (latin, then * latin-ext, then greek), whatever order they arrive in: the last one added * wins a character two files hold. Resolves to the number of faces added. */ async function loadFonts(faces, text = '', { optional = false } = {}) { kitStatus('Loading fonts…'); const ranges = kitRanges(); const jobs = []; for (const [family, specs] of Object.entries(faces)) { const id = fontsourceId(family); const todo = [...new Set(specs)].map((spec) => [parseInt(spec, 10), spec.endsWith('i') ? 'italic' : 'normal']) .filter(([weight, style]) => !hasFace(family, weight, style)); // before any await const at = fontsourceAt(id); const meta = optional || /[^\0-ÿ]/u.test(text) ? await fontsourceMeta(family) : null; const subsets = ['latin', ...kitSubsetsFor(text, meta)]; for (const [weight, style] of todo) { if (optional && !(meta?.weights.includes(weight) && meta.styles.includes(style))) continue; for (const subset of subsets) { const url = `${await at}files/${id}-${subset}-${weight}-${style}.woff2`; const face = new FontFace(family, `url(${url}) format('woff2')`, { weight: String(weight), style, unicodeRange: ranges[subset] }); jobs.push(face.load().catch(() => { if (subset === 'latin' && !optional) throw new Error(`Fontsource has no ${family} ${weight} ${style}`); })); } } } const ready = await Promise.all(jobs).catch((error) => { kitFail(error); throw error; }); return ready.filter((face) => face && document.fonts.add(face)).length; } /** A loaded FontFace covers this family, weight and style (fonts.check() would * also say yes for families nobody declared). */ function hasFace(family, weight, style) { for (const face of document.fonts) { if (face.status !== 'loaded' || face.style !== style) continue; if (face.family.replace(/^["']|["']$/g, '') !== family) continue; const [low, high = low] = face.weight.split(' ').map(Number); if (weight >= low && weight <= high) return true; } return false; } /** The files beyond latin `text` needs that `meta`'s family ships. */ function kitSubsetsFor(text, meta) { return [[/[Ā-˿ᴀ-ᶿḀ-ỿ†ℓⱠ-Ɀ꜠-ꟿ]/u, 'latin-ext'], [/[Ͱ-Ͽ]/u, 'greek']] .filter(([re, x]) => re.test(text) && meta?.subsets?.includes(x)).map(([, x]) => x); } /** Fontsource's id for a family: 'Source Serif 4' → 'source-serif-4'. */ function fontsourceId(family) { return family.toLowerCase().replace(/\s+/g, '-'); } /** A package's folder at the one version @5 names now (#766). */ function fontsourceAt(id, u = `https://cdn.jsdelivr.net/npm/@fontsource/${id}@`) { return (fontsourceAt.c ??= {})[id] ??= fetch(u + '5/package.json').then((r) => r.json()) .then((p) => p.version || 5, () => 5).then((v) => `${u}${v}/`); } /** The family's Fontsource metadata (weights, styles, subsets), or null. */ function fontsourceMeta(family) { fontsourceMeta.cache ??= new Map(); const id = fontsourceId(family); if (!fontsourceMeta.cache.has(id)) { fontsourceMeta.cache.set(id, fetch(`https://api.fontsource.org/v1/fonts/${id}`) .then((res) => (res.ok ? res.json() : null), () => null)); } return fontsourceMeta.cache.get(id); } // ─── Kit · viewer v2 ── the same in every recipe · postext.dev/cookbook /** The pages as spreads on a dark desk, page 1 alone, then verso | recto, * each painted when it scrolls near. Other options go to renderPageToCanvas. */ function showPages(docs, { title, width = 460, ...render } = {}) { const root = viewer(title); const pages = [docs].flat().flatMap((doc) => doc.pages.map((page) => ({ doc, page, n: (doc.pageIndexOffset ?? 0) + page.index }))); const spreads = []; let verso = null; for (const p of pages) { if (p.n % 2 === 1) { if (verso) spreads.push([verso, null]); verso = p; } else { spreads.push([verso, p]); verso = null; } } if (verso) spreads.push([verso, null]); const density = Math.min(window.devicePixelRatio || 1, 2); showPages.painter?.disconnect(); const painter = new IntersectionObserver((entries) => { for (const { isIntersecting, target } of entries) { if (!isIntersecting) continue; painter.unobserve(target); const { doc, page } = target.postext; renderPageToCanvas(page, doc, target, { ...render, scale: (width * density) / page.width }); } }, { rootMargin: '800px' }); showPages.painter = painter; root.replaceChildren(...spreads.map((pair) => { const spread = document.createElement('div'); spread.className = 'pt-spread'; for (const p of pair) { const figure = document.createElement('figure'); if (p) { const label = p.page.pageLabel || String(p.n + 1); const canvas = document.createElement('canvas'); canvas.postext = p; canvas.style.aspectRatio = `${p.page.width} / ${p.page.height}`; canvas.setAttribute('role', 'img'); canvas.setAttribute('aria-label', `Page ${label}`); const folio = document.createElement('figcaption'); folio.textContent = label; figure.append(canvas, folio); painter.observe(canvas); } else figure.className = 'pt-blank'; spread.append(figure); } return spread; })); kitStatus(`${pages.length} ${pages.length === 1 ? 'page' : 'pages'}`); document.documentElement.dataset.postext = 'ready'; return pages.length; } /** The desk, the bar and the error reporting, created once. */ function viewer(title) { if (!document.getElementById('pt-kit')) { document.head.insertAdjacentHTML('beforeend', `<style id="pt-kit"> :root { color-scheme: dark; } body { margin: 0; background: #0e1014; color: #b9bcc4; font: 13px/1.45 system-ui, sans-serif; } #pt-bar { position: sticky; top: 0; z-index: 1; display: flex; flex-wrap: wrap; align-items: center; gap: 6px 16px; padding: 10px 16px; background: rgb(14 16 20 / .92); backdrop-filter: blur(6px); border-bottom: 1px solid #23262d; } #pt-bar strong { color: #f4f1ea; font-weight: 600; } #pt-actions { display: flex; gap: 12px; margin-left: auto; } #pt-actions a, #pt-actions button { color: #d8a21a; font: inherit; background: none; border: 0; padding: 0; cursor: pointer; } #pages { display: grid; justify-items: center; gap: 48px; padding: 32px 16px 72px; } .pt-spread { display: flex; } .pt-spread figure { margin: 0; width: min(460px, 44vw); } .pt-spread canvas { display: block; width: 100%; background: #fff; box-shadow: 0 1px 2px rgb(0 0 0 / .5), 0 22px 44px -16px rgb(0 0 0 / .8); } .pt-spread figure:first-child canvas { box-shadow: inset -14px 0 14px -14px rgb(0 0 0 / .18), 0 1px 2px rgb(0 0 0 / .5), 0 22px 44px -16px rgb(0 0 0 / .8); } .pt-spread figcaption { margin-top: 10px; text-align: center; font: 600 10px/1 system-ui, sans-serif; letter-spacing: .18em; text-transform: uppercase; color: #6c7079; } .pt-blank { visibility: hidden; } @media (max-width: 760px) { .pt-spread { flex-direction: column; gap: 32px; } .pt-spread figure { width: min(460px, 92vw); } .pt-blank { display: none; } } </style>`); document.body.insertAdjacentHTML('afterbegin', '<header id="pt-bar"><strong id="pt-title"></strong><span id="pt-status" role="status"></span><span id="pt-actions"></span></header>'); document.getElementById('pt-title').textContent = document.title || 'Postext'; addEventListener('error', (event) => kitFail(event.error ?? event.message)); addEventListener('unhandledrejection', (event) => kitFail(event.reason)); } if (title) document.getElementById('pt-title').textContent = title; return document.getElementById('pages') ?? document.body.appendChild(Object.assign(document.createElement('main'), { id: 'pages' })); } function kitStatus(text) { viewer(); document.getElementById('pt-status').textContent = text; } function kitFail(error) { document.documentElement.dataset.postext = 'error'; kitStatus(`Error: ${error?.message ?? error}`); } // ─── Kit · pdf v3 ── the same in every recipe that exports a PDF /** The Fontsource files the screen used, as TrueType, with their range and * place: the nearest weight the family ships, upright with no italic; * latin, then what its letters need (kitSubsetsFor). */ async function fontsourceProvider(family, weight, style, request) { const id = fontsourceId(family); const meta = await fontsourceMeta(family); const weights = meta?.weights?.length ? meta.weights : [400, 700]; const w = weights.reduce((a, b) => (Math.abs(b - weight) < Math.abs(a - weight) ? b : a)); const s = style === 'italic' && meta && !meta.styles.includes('italic') ? 'normal' : style; const text = String.fromCodePoint(...(request?.codePoints ?? [])); const files = await Promise.all(['latin', ...kitSubsetsFor(text, meta)].map(async (subset, order) => { const res = await fetch(`${await fontsourceAt(id)}files/${id}-${subset}-${w}-${s}.woff2`); if (!res.ok) throw new Error(`Fontsource has no ${family} ${w} ${s} ${subset}`); return Object.assign(await decompressWoff2(new Uint8Array(await res.arrayBuffer())), { unicodeRange: kitRanges()[subset], order }); })); return files.length === 1 ? files[0] : files; } /** A "Build the PDF" button; then "Open the PDF" (a new tab: CodePen's frame * shows no PDFs) and a download link. */ function offerPdf(makePdf, filename) { viewer(); const button = Object.assign(document.createElement('button'), { type: 'button', textContent: 'Build the PDF' }); button.dataset.postextPdf = filename; button.addEventListener('click', async () => { button.disabled = true; button.textContent = 'Building the PDF…'; try { const bytes = await makePdf(); const url = URL.createObjectURL(new Blob([bytes], { type: 'application/pdf' })); const size = `${Math.max(1, Math.round(bytes.length / 1024))} KB`; button.replaceWith( Object.assign(document.createElement('a'), { href: url, target: '_blank', rel: 'noopener', textContent: 'Open the PDF ↗' }), Object.assign(document.createElement('a'), { href: url, download: filename, textContent: `Download ${filename} · ${size}` })); } catch (error) { button.disabled = false; button.textContent = 'Build the PDF'; kitFail(error); } }); document.getElementById('pt-actions').append(button); } // ─── Kit · images v3 ── recipes with pictures · postext.dev/cookbook /** Registers a photo or PNG for the canvas and keeps its bytes for the PDF. * fetch → ImageBitmap never taints the canvas (a plain cross-origin <img> would). */ async function loadImage(fileId, url) { const res = await fetch(url); if (!res.ok) throw new Error(`Image not found (${res.status}): ${url}`); const bytes = new Uint8Array(await res.arrayBuffer()); registerResourceImage(fileId, await createImageBitmap(new Blob([bytes]))); (loadImage.bytes ??= new Map()).set(fileId, bytes); } /** Registers SVG markup as a vector image, its fonts inside (inlineSvgFonts, ≥ 1.25). * `options` go to registerResourceImage: { singleInk: true } tints it on the canvas. */ async function loadSvg(fileId, svg, options) { if (typeof inlineSvgFonts === 'function') svg = await inlineSvgFonts(svg, svgFaces); const img = new Image(); img.src = `data:image/svg+xml;charset=utf-8,${encodeURIComponent(svg)}`; await img.decode(); registerResourceImage(fileId, img, options); (loadImage.bytes ??= new Map()).set(fileId, new TextEncoder().encode(svg)); } /** A face's Fontsource files: nearest weight; latin + what the SVG sets. */ async function svgFaces(family, weight, style, { codePoints = [] } = {}) { const [id, m] = [fontsourceId(family), await fontsourceMeta(family)]; const w = m?.weights.reduce((a, b) => (Math.abs(b - weight) < Math.abs(a - weight) ? b : a)) ?? weight; const s = m?.styles.includes(style) === false ? 'normal' : style; return Promise.all(['latin', ...kitSubsetsFor(String.fromCodePoint(...codePoints), m)].map(async (x) => new Uint8Array( await (await fetch(`${await fontsourceAt(id)}files/${id}-${x}-${w}-${s}.woff2`)).arrayBuffer()))); } /** renderToPdf({ resourceBytes: imageBytes }) */ function imageBytes(fileId) { return loadImage.bytes?.get(fileId); } /** renderToHtml({ resourceImageUrl: imageUrl }) */ function imageUrl(fileId) { const bytes = imageBytes(fileId); if (!bytes) return undefined; imageUrl.urls ??= new Map(); if (!imageUrl.urls.has(fileId)) { const type = /\.svg$/i.test(fileId) ? 'image/svg+xml' : /\.png$/i.test(fileId) ? 'image/png' : 'image/jpeg'; imageUrl.urls.set(fileId, URL.createObjectURL(new Blob([bytes], { type }))); } return imageUrl.urls.get(fileId); } // ─── Kit · cjk v2 ── Chinese, Japanese and Korean books · postext.dev/cookbook // Fontsource ships a CJK family as about a hundred files per weight, each // declared in its stylesheet with the unicode-range it covers. The screen // loads the files the sample touches; the PDF gets the same files for the // characters its pages set in each face, and embeds each as a subset. // A book bound on the right (vertical text) is shown with its spreads // mirrored: page 1 alone on the left of the spine, then [3 | 2]. /** The files of a Fontsource face, read from its stylesheet: { url, range, * ranges }, the last declared first (the order the browser tries them in). */ function cjkSlices(family, weight, style) { cjkSlices.cache ??= new Map(); const id = fontsourceId(family); const css = `${id}/${weight}${style === 'italic' ? '-italic' : ''}.css`; if (!cjkSlices.cache.has(css)) { let at; cjkSlices.cache.set(css, fontsourceAt(id).then((a) => fetch(at = a + css.slice(id.length + 1))) .then((res) => { if (!res.ok) throw new Error(`Fontsource has no ${family} ${weight} ${style} (${res.status})`); return res.text(); }) .then((text) => [...text.matchAll(/@font-face\s*{([^}]*)}/g)].map(([, rule]) => { const range = /unicode-range:\s*([^;]+);/.exec(rule)?.[1].trim() ?? 'U+0-10FFFF'; const ranges = range.split(',').map((part) => { const [lo, hi = lo] = part.trim().slice(2).split('-'); return [parseInt(lo, 16), parseInt(hi, 16)]; }); return { url: new URL(/url\(([^)]+?\.woff2)\)/.exec(rule)[1], at).href, range, ranges }; }).reverse())); } return cjkSlices.cache.get(css); } /** The file of `slices` the screen sets code point `cp` in, if any: the * last one loadCjkFonts adds whose range holds it. A numbered file that * repeats a letter of latin is added after latin, and wins it. */ function cjkSliceFor(slices, cp) { const holds = (slice) => slice.ranges.some(([lo, hi]) => cp >= lo && cp <= hi); return slices.reduce((last, slice) => (holds(slice) ? slice : last), undefined); } /** Whether Fontsource serves `family` as a Chinese, Japanese or Korean * family (its subsets name the script). Fails when the API does not * answer: a CJK face taken for a Latin one would paint in a system face. */ async function isCjkFamily(family) { const meta = await fontsourceMeta(family); if (!meta) throw new Error(`api.fontsource.org did not describe ${family}: reload to try again`); return !!meta.subsets?.some((subset) => /^(chinese|japanese|korean)/.test(subset)); } /** faces = { 'Noto Serif TC': ['400', '700'] }, as for loadFonts: the * whole FONTS object may be passed, its other families are left to * loadFonts. Adds one FontFace per file of each CJK face with its * unicodeRange, then loads the files `text` touches. `text` is what the * faces set: the sample for the text face; a book in several voices calls * it once per voice (loadCjkFonts({ 'LXGW WenKai TC': ['400'] }, quotes)), * so the heading and quotation faces fetch and check only their own * characters. Fails when a character of `text` is in no file of a face. * List every weight the pages use: a weight left to the engine's later round * gets the latin file only. With { vertical: true } it also loads each * family's vertical forms (brackets, quotes, pause marks) for the canvas, * which needs loadVerticalAlternates imported from postext. Resolves to * the number of files loaded. */ async function loadCjkFonts(faces, text, { vertical = false } = {}) { kitStatus('Loading fonts…'); let loaded = 0; try { if (vertical && typeof loadVerticalAlternates !== 'function') { throw new Error('loadCjkFonts(…, { vertical: true }) needs loadVerticalAlternates imported from postext'); } for (const [family, specs] of Object.entries(faces)) { if (!(await isCjkFamily(family))) continue; const twin = []; for (const spec of new Set(specs)) { const weight = parseInt(spec, 10); const style = spec.endsWith('i') ? 'italic' : 'normal'; const slices = await cjkSlices(family, weight, style); const missing = [...new Set(text)].filter((ch) => /\S/.test(ch) && !cjkSliceFor(slices, ch.codePointAt(0))); if (missing.length) { throw new Error(`${family} ${spec} has no file for ${missing.slice(0, 12).join(' ')}: ` + `give each face the text it sets (loadCjkFonts({ '${family}': ['${spec}'] }, text))`); } for (const slice of slices) { document.fonts.add(new FontFace(family, `url(${slice.url}) format('woff2')`, { weight: String(weight), style, unicodeRange: slice.range })); twin.push({ source: slice.url, weight: String(weight), style, unicodeRange: slice.range }); } const font = `${style === 'italic' ? 'italic ' : ''}${weight} 16px "${family}"`; loaded += (await document.fonts.load(font, text)).length; if (!document.fonts.check(font, text)) throw new Error(`${family} ${spec} did not load for the sample`); } // The same files under a twin name with the `vert` feature on: the // canvas paints the punctuation of vertical lines with it. if (vertical && twin.length) await loadVerticalAlternates(family, twin); } } catch (error) { kitFail(error); throw error; } return loaded; } /** The PDF font provider for recipes with CJK faces: a family whose * Fontsource subsets are Chinese, Japanese or Korean gets the files the * screen set its pages' characters in (`request.codePoints`), each marked * with its unicode-range and its place in the order loadCjkFonts added * them: postext-pdf sets a character two files hold in the one added * last, as the browser does. Any other family gets the latin file * fontsourceProvider fetches (the "pdf" block) and, when the face sets * letters only latin-ext has, that file too. */ async function cjkPdfProvider(family, weight, style, request) { if (!(await isCjkFamily(family))) return cjkLatinPdfFiles(family, weight, style, request); const meta = await fontsourceMeta(family); const weights = meta.weights?.length ? meta.weights : [400, 700]; const w = weights.reduce((a, b) => (Math.abs(b - weight) < Math.abs(a - weight) ? b : a)); const s = style === 'italic' && !meta.styles.includes('italic') ? 'normal' : style; const slices = await cjkSlices(family, w, s); const picked = new Set(); for (const cp of request?.codePoints ?? []) { const slice = cjkSliceFor(slices, cp); if (slice) picked.add(slice); } if (!picked.size) picked.add(slices[0]); return Promise.all(slices.map(async (slice, order) => { if (!picked.has(slice)) return null; const res = await fetch(slice.url); if (!res.ok) throw new Error(`Fontsource file ${slice.url} (${res.status})`); const bytes = await decompressWoff2(new Uint8Array(await res.arrayBuffer())); return Object.assign(bytes, { unicodeRange: slice.range, order }); })).then((files) => files.filter(Boolean)); } /** A Latin family set next to the CJK faces: its latin file, then its * latin-ext file when the face sets letters only latin-ext has (ō ū in * Hepburn rōmaji, ǎ in pinyin), the file loadFonts adds on screen for * them, each marked with its unicode-range and its place in that order: * the PDF sets a character in the file the browser took it from. A face * Fontsource ships without latin-ext, or whose file does not come, gets * latin alone, and the PDF names the letters it lacks. */ async function cjkLatinPdfFiles(family, weight, style, request) { const meta = await fontsourceMeta(family); const beyond = [...(request?.codePoints ?? [])].some(cjkLatinExtOnly); if (!beyond || !meta?.subsets?.includes('latin-ext')) return fontsourceProvider(family, weight, style); const weights = meta.weights?.length ? meta.weights : [400, 700]; const w = weights.reduce((a, b) => (Math.abs(b - weight) < Math.abs(a - weight) ? b : a)); const s = style === 'italic' && !meta.styles.includes('italic') ? 'normal' : style; const id = fontsourceId(family); const url = `${await fontsourceAt(id)}files/${id}-latin-ext-${w}-${s}.woff2`; const [latin, ext] = await Promise.all([fontsourceProvider(family, weight, style), fetch(url) .then(async (res) => (res.ok ? decompressWoff2(new Uint8Array(await res.arrayBuffer())) : null), () => null)]); const ranges = kitRanges(); return ext ? [Object.assign(latin, { unicodeRange: ranges.latin, order: 0 }), Object.assign(ext, { unicodeRange: ranges['latin-ext'], order: 1 })] : latin; } /** Whether code point `cp` is in Fontsource's latin-ext file and not in * its latin file: Latin Extended-A and -B, IPA, the spacing modifiers and * Latin Extended Additional (loadFonts's test for latin-ext), less the * few latin holds too (ı Œ œ ʻ ʼ ˆ ˚ ˜). */ function cjkLatinExtOnly(cp) { if (!((cp >= 0x100 && cp <= 0x2ff) || (cp >= 0x1e00 && cp <= 0x1eff))) return false; return ![0x131, 0x152, 0x153, 0x2bb, 0x2bc, 0x2c6, 0x2da, 0x2dc].includes(cp); } /** showPages for a book bound on either edge. A right-bound book (the * document says so: doc.binding is 'right' for page.binding 'right' and * for vertical text) lies on the desk as it opens: page 1 alone on the * left of the spine, then [3 | 2], the spine shade on each page's inner * edge. `binding` ('left' | 'right') overrides the document's. */ function showBook(docs, { binding, ...options } = {}) { const count = showPages(docs, options); const right = (binding ?? [docs].flat()[0]?.binding) === 'right'; if (!document.getElementById('pt-kit-cjk')) { // The pages keep direction ltr: a canvas draws text in the direction its // element inherits, and under rtl each run would end where the engine // starts it, its brackets mirrored. document.head.insertAdjacentHTML('beforeend', `<style id="pt-kit-cjk"> .pt-spread[dir="rtl"] canvas { direction: ltr; } .pt-spread[dir="rtl"] figure:first-child canvas { box-shadow: inset 14px 0 14px -14px rgb(0 0 0 / .18), 0 1px 2px rgb(0 0 0 / .5), 0 22px 44px -16px rgb(0 0 0 / .8); } </style>`); } // Each pair stays [verso, recto] in the page; right to left, the verso // sits on the right. Phones stack the pages in reading order either way. for (const spread of document.querySelectorAll('#pages > .pt-spread')) spread.dir = right ? 'rtl' : 'ltr'; document.getElementById('pages').dataset.binding = right ? 'right' : 'left'; return count; } // ─── /Kit ───────────────────────────────────────────────────────────────────────
Le script.js composé s’exécute tel quel : collez-le dans le script de module de n’importe quelle page, ou ouvrez la recette sur CodePen. Dossier de la recette sur GitHub ↗ (s’ouvre dans un nouvel onglet)
Variantes
#Laisser les petits kana et ー commencer une ligne
ja-strict est la règle de JLReq pour les livres généraux : っ, ゃ et ー peuvent ouvrir une ligne, ce qui donne à l’algorithme de coupure plus d’endroits où couper et moins de lignes espacées.
-  lineBreak: 'ja-very-strict', // no line starts with ー, small kana, 々, 」、。?・ or :
+ lineBreak: 'ja-strict', // small kana, ー and 々 may open a line#Pas d’espace entre japonais et latin
Certains éditeurs composent les mots latins collés aux kana, sans quart de cadratin.
-  latinSpacing: em(0.25), // 四分アキ between kana or kanji and Latin letters or digits
+ latinSpacing: em(0), // Unicodeでは, set solidErreurs fréquentes
Erreur fréquente
Balisez un texte japonais 'ja', jamais zh-Hans ni LANG
Les éditions d’une recette sont en et es, mais un exemple japonais est en japonais dans les deux : `locale: LANG` le baliserait en anglais ou en espagnol, et une balise chinoise le composerait selon les règles chinoises (ponctuation Kaiming, petits kana libres de commencer une ligne, 图 pour 図, formes de glyphes chinoises dans le PDF). Depuis postext 1.30, la balise est aussi la langue dans laquelle le texte est mis en forme (mesuré, peint et incorporé) : toute balise autre que 'ja' donne d’autres formes de glyphes que les japonaises (les chinoises sous une balise chinoise) et d’autres coupures de ligne. Écrivez 'ja' : elle choisit la région Japon (coupure des lignes et ponctuation JLReq, points d’emphase sésame, espacement des furigana, étiquettes 図 et 表) et désactive la césure. Le lint fait échouer un texte contenant des kana sous une balise zh ou ko. Coupure des lignes en japonais (kinsoku) →
Erreur fréquente
Composez le japonais dans un caractère japonais
Noto Serif SC et TC ont des kana, mais ils dessinent les kanji sous leurs formes chinoises (直, 骨 et 角 diffèrent) et les kana dans un dessin chinois. Composez le texte en Noto Serif JP ou Shippori Mincho B1 et les titres en Noto Sans JP, chargés avec loadCjkFonts. Les fichiers japonais de Fontsource ne contiennent ni hentaigana ni autres kana historiques (U+1B000–1B16F) : loadCjkFonts échoue sur eux et le PDF imprime des cases. Écrivez donc les kana modernes, ou livrez dans les ressources de la recette un caractère qui les possède. Shippori Mincho n’a pas non plus les voyelles à macron ō et ū : composez le rōmaji dans un caractère latin. Kana, kanji et rōmaji →
Erreur fréquente
Les polices chinoises se chargent par tranches, avec le bloc cjk
Fontsource sert une famille chinoise, japonaise ou coréenne sous la forme d’une centaine de fichiers par graisse, chacun couvrant une plage de caractères. loadFonts ne récupère que le fichier latin : à l’écran, les caractères han viennent d’une police système et sont mal mesurés, et fontsourceProvider remet ce fichier latin au PDF, qui les imprime en cases vides. Listez le bloc cjk du kit, appelez loadCjkFonts(FONTS, markdown) après loadFonts (une fois par voix, avec le texte qu’elle compose, quand le livre utilise plusieurs polices CJK) et donnez à renderToPdf fontProvider: cjkPdfProvider : les deux prennent les fichiers qui contiennent les caractères du texte. Polices chinoises, japonaises et coréennes →
- Un mot latin ne peut pas se couper dans une ligne japonaise : un mot long en fin de ligne laisse la ligne précédente espacée entre ses caractères. Le premier jet de ce chapitre glosait ses termes en anglais, 正準等価(canonical equivalence), et deux lignes en sont sorties lâches ; les termes anglais ont été retirés là où ils n’aidaient pas le lecteur.
- Choisissez le caractère de code selon les caractères que contient le code. M PLUS 1 Code, le premier essayé ici, n’a pas de katakana demi-chasse : l’écran se rabattait sur une police système pour ガイド et il manquait les glyphes au PDF.
- Un listing se coupe entre ses lignes d’une page à l’autre, avec au moins deux lignes de chaque côté (
codeStyle.splitMinLines). Page 43, la place restant sous 3.3 contient le titre et une seule ligne, pas deux : le listing entier ouvre donc la page 44 ;keepTogether: truegarde chaque listing d’un seul tenant. - Sur une grille de caractères, une page prend ses 29 lignes quoi que fasse un paragraphe ou une liste au changement de page : la liste des quatre formes laisserait donc son premier élément, NFC, seul au pied de la page 42.
shortListSplit: 'avoid'avecshortListMaxItems: 4fait passer toute la liste en page 43, et la page 42 finit une ligne plus haut, au-dessus de ses notes.
Crédits
- Recette
- Ignacio Ferro
- Texte
- Texte original, CC BY 4.0
- Images
- Figure 3-1, the bytes of が, drawn in code in the page’s palette · Postext Cookbook · CC BY 4.0
- Polices
- Noto Serif JP (SIL OFL 1.1) · Noto Sans JP (SIL OFL 1.1) · BIZ UDGothic (SIL OFL 1.1)
Modifier ce texte ↗ (s’ouvre dans un nouvel onglet)Dossier de la recette sur GitHub ↗ (s’ouvre dans un nouvel onglet)