In short
A short reader of a classic Chinese novel with an index of its characters' names. The same marks give two editions: one sorted by sound, one by number of pen strokes.
What you'll build
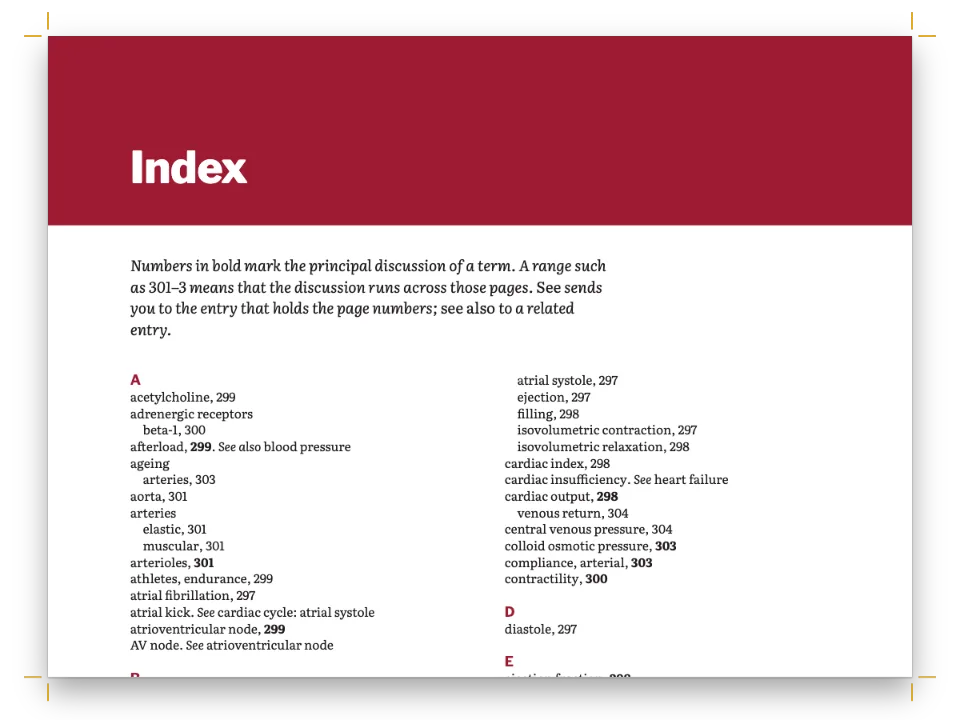
A slim reader of 紅樓夢 (Dream of the Red Chamber) that reprints, from chapters 1 to 3, the passages where the cast first appears, and ends with an index of its 47 names, plus four cross-references from other names. It comes in two editions from the same marks. The mainland one, in Simplified characters, files the names under their pinyin initial, F, H, J…; the Taiwan one, in Traditional characters, under the stroke count of the first character, 三畫, 四畫… Both are 大32开 paperbacks, 140 × 203 mm, 26 characters to the line in Noto Serif, with the chapter titles in a Kai face and the kickers, folios and index heads in Noto Sans. The card enlarges the first groups of the Simplified index, F to L. An index of names and an index of subjects builds the same kind of index for an English monograph.
This recipe answers
- How do I group an index of Chinese names by pinyin or by stroke count?
- How do I get Chinese characters into the PDF without empty boxes?
The short answer
// Marks in the Markdown, one per passage; main is the page where the character enters:
//   字:index[士隐]{term="甄士隐" main}      :index{term="贾化" see="贾雨村"}
// Printed at the end of each edition: # 人名索引 {style="index"}, then :::index
const index = (e) => ({
  // 'auto' reads the same from the locale: pinyin for zh-Hans, strokes for zh-Hant.
  groupBy: e.locale === 'zh-Hans' ? 'pinyin' : 'stroke', // A B C… or 三畫 四畫…
  fontFamily: e.serif, fontSize: pt(9), lineHeight: pt(14),
  separator: '\u3000', locatorSeparator: ',', // 贾宝玉 4,6: an ideographic space, then ,
  see: { italic: false }, // 见 / 見 upright: Chinese has no italic (gotcha: cjk-no-italic)
  groups: { fontFamily: e.sans, fontSize: pt(9.5), fontWeight: 700, color: col('cinnabar'),
    marginTop: pt(6.25) }, // the three names of 九畫 stay whole at the foot of their column
});
const indexHeading = { id: 'index', numbered: false, breakBefore: { enabled: true, parity: 'any' },
  layout: { layoutType: 'double', gutterWidth: pt(21) } }; // two columns, 2 characters apart
The same marks, grouped by pinyin in zh-Hans and by strokes in zh-Hant
Ingredients
- Features
- Back-of-book indexChinese, Japanese and Korean fontsHeading stylesUnnumbered chaptersDesigned openersHeading attributesChinese numeralsCharacter gridChinese line breakingRunning heads and foliosMirrored marginsColumn balancingParagraph stylesSemantic colour palettePDF export
- Also uses
- Paper colourHeads by page roleFonts embedded in the PDFSection geometryLine breaks in titles
- Type
- Noto Serif SC, Noto Sans SC, Ma Shan Zheng, Noto Serif TC, Noto Sans TC, LXGW WenKai TC (SIL OFL 1.1)
- Assets
- None: every picture is drawn in code
Method
#1 · Mark each name where the reader meets it
The code is the short answer above; the rest is in the Markdown. A mark files the full name whatever the text prints: 字:index[士隐]{term="甄士隐" main} prints 士隐 and files a page under 甄士隐. main makes the page bold, and the note under the index title says what bold means here: the page where the character enters in person. Jia Baoyu is born in chapter 2 without being named (又生了一位公子), so the mark goes in with nothing to print, :index{term="贾宝玉"}, and his entry reads 4, 6. Other names and nicknames get a cross-reference of their own, :index[凤辣子]{term="凤辣子" see="王熙凤"}, which Postext prints the Chinese way, after a full stop and with no space: 凤辣子。见王熙凤 (Index marks).
#2 · Let the locale choose the order
// The mainland edition in Simplified characters and the Taiwan edition in Traditional ones.
// Each takes the Song (serif), Hei (sans) and Kai faces cut for its script. Fontsource has no
// Kai text face with mainland forms: LXGW WenKai TC draws 冷 the Taiwan way, so the mainland
// titles take Ma Shan Zheng, a brush Kai.
const EDITIONS = {
  hans: { locale: 'zh-Hans', serif: 'Noto Serif SC', sans: 'Noto Sans SC', kai: 'Ma Shan Zheng' },
  hant: { locale: 'zh-Hant', serif: 'Noto Serif TC', sans: 'Noto Sans TC', kai: 'LXGW WenKai TC' },
};
The two editions share the configuration, and locale is the only switch the index needs: groupBy: 'auto' groups a zh-Hans index by pinyin and a zh-Hant one by strokes, and the short answer writes the two values out so you can see them. The entries sort in the order the heads come from, so the same names change places: 甄费 comes before 甄士隐 under Z (fèi before shì), and after it under 十四畫 (士 has three strokes, 費 twelve); 宁国公 and 荣国公 part for N and R, while 寧國公 and 榮國公 stay together among the fourteen-stroke names (Back-of-book index). The readings and stroke counts are the browser's Chinese collation; a surname it reads wrong (曾, 单, 解) takes a sort key in characters with the right reading.
#3 · Load each face with the characters it sets
const DIGITS = '0123456789';
const HEADS = '第回一二三四五六七八九十画畫ABCDEFGHIJKLMNOPQRSTUVWXYZ'; // 第一回, the index heads
const all = (md, re) => [...md.matchAll(re)].map((m) => m[1]).join('\n');
for (const [key, md] of [['hans', markdown], ['hant', traditional]]) {
  e = EDITIONS[key];
  await loadCjkFonts({ [e.serif]: ['400'] }, md); // the text, the index, the running heads
  await loadCjkFonts({ [e.serif]: ['700'] }, DIGITS); // the bold page numbers
  await loadCjkFonts({ [e.sans]: ['700'] }, all(md, /kicker="([^"]*)"/g) + HEADS + DIGITS);
  await loadCjkFonts({ [e.kai]: ['400'] }, all(md, /^# ([^{\n]*)/gm)); // the titles alone
}
Fontsource cuts each Chinese weight into about a hundred files, and loadCjkFonts fetches the ones its text touches. The Song face gets the whole book, so the running heads cost it nothing; its bold, the digits of the principal pages; the Hei face, the text of the kicker attributes, the index heads and the digits of the folios; the Kai face, the three couplets and 人名索引. The PDF takes the same route: cjkPdfProvider embeds those files, each cut down to the characters its pages use, and no character comes out as an empty box. The Kai face changes with the edition. LXGW WenKai TC, the only Kai text face on Fontsource, draws inherited forms, 冷 with the old 卩 foot of 令, and centres its commas and full stops, so the Simplified titles are set in Ma Shan Zheng, a brush Kai with the mainland forms (Chinese, Japanese and Korean fonts).
#4 · Put the note in the index opener
const opener = (e, sink, kicker, note = []) => ({
  enabled: true,
  minHeight: pt(LEAD * sink), // the text starts on the same line after every opener
  slot: { elements: [
    { kind: 'text', id: 'kicker', content: kicker, fontFamily: e.sans, fontSize: pt(9),
      fontWeight: 700, letterSpacing: pt(2.7), color: col('cinnabar'), align: 'center',
      placement: { ...at('container', 'top', 0, 8), size: { width: 'fill', height: 'auto' } } },
    { kind: 'text', id: 'title', content: '{titleText}', fontFamily: e.kai, fontSize: pt(16),
      lineHeight: 1.45, color: col('ink'), align: 'center',
      overflow: 'wrap', // design text ends in an ellipsis by default
      placement: { ...at('#kicker', 'below', 0, 3), size: { width: 'fill', height: 'auto' } } },
    { kind: 'rule', id: 'rule', direction: 'horizontal', thickness: pt(0.5), color: col('rule'),
      placement: { ...at('#title', 'below', (MEASURE - 12) / 2, 4), size: { width: mm(12) } } },
    ...note,
  ] },
});
// The note (note="…" on the heading) sits above the columns: no paragraph for balancing to loosen.
const indexNote = (e) => [{ kind: 'text', id: 'note', content: '{attr.note}',
  fontFamily: e.serif, fontSize: pt(9), lineHeight: 1.6, color: col('muted'), align: 'center',
  overflow: 'wrap', placement: { ...at('#rule', 'below', -(MEASURE - 12) / 2, 4),
    size: { width: 'fill', height: 'auto' } } }];
The note is an attribute of the heading, # 人名索引 {style="index" kicker="按汉语拼音排列" note="…"}, set across the whole measure above the two columns. As a paragraph inside the columns it was a lever for column balancing: to even out the Traditional edition's last page, the layout loosened it to twelve characters a line in a column of fourteen. The note is one sentence, 本索引收录前三回选文中的人物,粗体页码为人物出场之页;别名与原名另立参见条目。, wrapped by the design: design text in a Chinese book takes the body's line-breaking rules and mark widths, so ,; are half width in the Simplified edition and full width in the Traditional one, as in the text, and no line of the note opens with a mark. The chapter openers use the same design, with 第{numberHan}回 as the kicker, which prints 第一回 in the script of the document.
#5 · Show both index pages side by side
const indexPage = (doc) => doc.pages[doc.blocks.find((b) => b.headingStyleId === 'index')
  ?.pageIndex ?? doc.pages.length - 1];
const labels = { hans: t({ en: 'Simplified · by pinyin', es: 'Simplificado · por pinyin' }),
  hant: t({ en: 'Traditional · by strokes', es: 'Tradicional · por trazos' }) };
document.getElementById('pages').insertAdjacentHTML('beforebegin', `<section id="indexes" style="
  display:flex;flex-wrap:wrap;justify-content:center;gap:24px;padding:28px 16px;background:#e9e4da">
  ${Object.keys(docs).map((key) => `<figure style="margin:0;width:min(340px,44vw)">
  <canvas id="index-${key}" role="img" style="display:block;width:100%;background:#fff;
  box-shadow:0 18px 36px -18px rgb(0 0 0 / .45)"></canvas><figcaption style="margin-top:10px;
  font:600 11px/1 system-ui,sans-serif;letter-spacing:.14em;text-transform:uppercase;color:#5b534a">
  ${labels[key]}</figcaption></figure>`).join('')}</section>`);
for (const [key, doc] of Object.entries(docs)) {
  const canvas = document.getElementById(`index-${key}`);
  const page = indexPage(doc);
  canvas.setAttribute('aria-label', `${labels[key]}, ${page.pageLabel}`);
  renderPageToCanvas(page, doc, canvas, { scale: (2 * canvas.clientWidth) / page.width });
}
The pen builds both editions and shows the Simplified one on the desk. The 简体版 and 繁體版 buttons switch the desk, and each switch offers the PDF of the edition on it, chinese-name-index-hans.pdf or chinese-name-index-hant.pdf. The capture records both builds (capture.doc: ['first', 'last']): the first eight pages above are the Simplified edition, and the four after them come from the Traditional one, its first page and its stroke index. The strip above the desk holds the first index page of each edition. The PDF offered with the recipe is the Simplified edition's.
The whole recipe
// ═══ Postext Cookbook · Nº 079 · An index of Chinese names, by pinyin and by strokes ═══
// https://postext.dev/en/cookbook/chinese-name-index
// Code: MIT · Text: 紅樓夢 (1792), zh.wikisource revision 9685985 (CC BY-SA 4.0) · Pictures: none
// Fonts: Noto Serif/Sans SC/TC, Ma Shan Zheng, LXGW WenKai TC (OFL 1.1) · Needs postext ≥ 1.28.0
import { buildDocument, withLoadedFonts, renderPageToCanvas } from 'https://esm.sh/postext';
import { renderToPdf, decompressWoff2 } from 'https://esm.sh/postext-pdf';

const LANG = 'en'; // @lang: the language of the sample document ('en' | 'es')
const RECIPE = 'chinese-name-index';

// ─── 1 · Design ─────────────────────────────────────────────────────────────
// #region palette: ink on a warm paper, one cinnabar for the heads and the index letters
const palette = {
  ink: '#1f1b18', // text
  cinnabar: '#a3301f', // the one accent: 回 numbers, index heads
  muted: '#6b635a', // running heads, folios, colophon
  rule: '#d6cdbf', // the short rule under each title
  paper: '#fbf8f1',
};
// Each colour carries its hex and the palette entry it follows.
const col = (id) => ({ hex: palette[id], model: 'hex', paletteId: id });
const colorPalette = [
  ...Object.entries(palette).map(([id, hex]) => ({ id, name: id, value: { hex, model: 'hex' } })),
  // The engine's defaults link to main-color: point it at the accent, never the default blue.
  { id: 'main-color', name: 'accent (defaults)', value: { hex: palette.cinnabar, model: 'hex' } },
];
// #endregion

// #region editions: one book, two scripts; the locale decides the index order
// The mainland edition in Simplified characters and the Taiwan edition in Traditional ones.
// Each takes the Song (serif), Hei (sans) and Kai faces cut for its script. Fontsource has no
// Kai text face with mainland forms: LXGW WenKai TC draws 冷 the Taiwan way, so the mainland
// titles take Ma Shan Zheng, a brush Kai.
const EDITIONS = {
  hans: { locale: 'zh-Hans', serif: 'Noto Serif SC', sans: 'Noto Sans SC', kai: 'Ma Shan Zheng' },
  hant: { locale: 'zh-Hant', serif: 'Noto Serif TC', sans: 'Noto Sans TC', kai: 'LXGW WenKai TC' },
};
// #endregion
const LEAD = 18; // body leading in pt: 1.7 × the 10.5 pt text (五号)
const MEASURE = (26 * 10.5 * 25.4) / 72; // the grid's 26 characters of 10.5 pt, in mm
const at = (to, edge, x = 0, y = 0) => ({ anchor: { to, edge }, offset: { x: mm(x), y: mm(y) } });

// #region answer: the same marks, grouped by pinyin in zh-Hans and by strokes in zh-Hant
// Marks in the Markdown, one per passage; main is the page where the character enters:
//   字:index[士隐]{term="甄士隐" main}      :index{term="贾化" see="贾雨村"}
// Printed at the end of each edition: # 人名索引 {style="index"}, then :::index
const index = (e) => ({
  // 'auto' reads the same from the locale: pinyin for zh-Hans, strokes for zh-Hant.
The composed script.js runs as it is: paste it into any page’s module script, or open the recipe on CodePen. Recipe folder on GitHub ↗ (opens in a new tab)
Variations
#Group a Traditional index by pinyin
A Traditional edition for readers who look names up by their reading can file them by pinyin. Set groupBy: 'pinyin' in both editions: the heads are A–Z and the entries keep their Traditional forms. The kicker says how the index is ordered, so change it in the Traditional Markdown too, to kicker="依漢語拼音排列".
-  groupBy: e.locale === 'zh-Hans' ? 'pinyin' : 'stroke', // A B C… or 三畫 四畫…
+ groupBy: 'pinyin', // A B C… in both scripts#Print the names without heads
A short list of names reads well with a blank line between groups and no head over them. Keep the grouping and turn the heads off. groupBy: 'none' would not do it: it sets apart only symbols, numbers and words, and every name here starts with a Han character, so the 47 would run as one block.
-  groups: { fontFamily: e.sans, fontSize: pt(9.5), fontWeight: 700, color: col('cinnabar'),
-    marginTop: pt(6.25) }, // the three names of 九畫 stay whole at the foot of their column
+ groups: { enabled: false, marginTop: pt(14) }, // no heads; a blank line between groupsPitfalls
Pitfall
Chinese faces load by slices, through the cjk block
Fontsource serves a Chinese, Japanese or Korean family as about a hundred files per weight, each covering a range of characters. loadFonts fetches only the latin file, so on screen the Han characters come from a system face and measure wrong, and fontsourceProvider hands the PDF that latin file, which prints them as empty boxes. List the cjk kit block, call loadCjkFonts(FONTS, markdown) after loadFonts (once per voice, with the text it sets, when the book uses several CJK faces) and give renderToPdf fontProvider: cjkPdfProvider: both take the files that hold the text's characters. Chinese, Japanese and Korean fonts →
Pitfall
Chinese has no italic
The CJK families ship no italic, and Chinese typography marks emphasis with dots beside the characters, not with a slant. In a document tagged Chinese, *…* sets emphasis dots on the Chinese characters it holds and keeps italics for the Latin words (cjk.emphasis: 'dots', the default for Chinese); :dots[…] sets them anywhere. With cjk.emphasis: 'italic', or in a document tagged en or es, *…* makes the canvas slant the upright glyphs, a synthetic oblique that Chinese typography never uses (the PDF falls back to the upright face): keep the Chinese tag, or set emphasis in bold or in a Kai face (LXGW WenKai) through a paragraph or chip style. Chinese, Japanese and Korean fonts →
Pitfall
Tag the document zh-Hans or zh-Hant, not with LANG
A recipe's editions are en and es, but a Chinese sample is Chinese in both: `locale: LANG` would tag it English or Spanish, hyphenate its Latin words, label its figures Figure or Figura and give the PDF the wrong language. From postext 1.30 the tag is also the language the text is shaped in (measured, painted and embedded), so under an English or Spanish tag a Chinese face sets its digits and the punctuation it shares with Latin text in other forms, and the lines break elsewhere. Write the tag yourself: 'zh-Hans' (mainland conventions: GB line breaking, Kaiming punctuation) or 'zh-Hant' (Taiwan: full-width centred punctuation); 'zh-HK' for Hong Kong. A bare 'zh' reads as Simplified, mainland. A Japanese sample takes 'ja' (gotcha ja-locale-tag). Chinese line breaking →
Pitfall
Set each region's punctuation in a face of that region
The punctuation widths move the blank beside each mark to the side the document's region puts it, not the side the font draws it: under zh-Hans a Kaiming comma keeps the left half of its box, where a Simplified face draws the glyph, and gives up the right half. A Traditional face centres ,。 in the box, so the half that goes holds part of the glyph and the comma crowds the next character. LXGW WenKai TC, the only Kai text face on Fontsource, does this in Simplified text. Set mainland text, notes and quotations in Noto Serif SC or Noto Sans SC, keep the TC faces for zh-Hant, and use a Simplified brush face (Ma Shan Zheng) only for display lines, where design text applies no punctuation widths. It also draws inherited forms that neither the mainland nor the Taiwan standard prints, 為 with the 爫 top of 爲 and 令 (in 冷, 領) with a 卩 foot: check the characters a page sets in it. Chinese punctuation widths →
- The
indexconfiguration belongs to the document, so one document prints one order. A book that wants both a pinyin index and a stroke finding list builds twice, as this pen does. - On a character grid column balancing is off by default, and the last page of each index would fill its first column to the foot: the Simplified edition's colophon would start under Z and finish at the head of the second column.
headings.balancing: { enabled: true }cuts the first column of that page short, so the names run on into the second and the colophon stays whole under them (Column balancing). The cut falls between entries and never leaves one name of a group alone at the foot or the head of a column (index.groups.splitMinEntries, 2 by default), so the two columns end level only where the lengths allow it. Here each colophon carries a sentence on the order of its index, and the columns of both closing pages end within a third of a line.
Credits
- Recipe
- Ignacio Ferro
- Text
- Dream of the Red Chamber (紅樓夢), chapters 1–3, passages where the characters first appear, in the Cheng–Gao edition of 1792 (程乙本); Wikisource transcription, revision 9685985. The Traditional edition reads the source's 原系 as 原係; both set its -- as ——; the Simplified edition converted with OpenCC · Cao Xueqin, Cheng Weiyuan and Gao E; transcription by Wikisource editors · CC BY-SA 4.0
- Fonts
- Noto Serif SC (SIL OFL 1.1) · Noto Sans SC (SIL OFL 1.1) · Ma Shan Zheng (SIL OFL 1.1) · Noto Serif TC (SIL OFL 1.1) · Noto Sans TC (SIL OFL 1.1) · LXGW WenKai TC (SIL OFL 1.1)
Edit this write-up ↗ (opens in a new tab)Recipe folder on GitHub ↗ (opens in a new tab)