In short
A chapter from a Japanese programming book, where Japanese sentences are full of English words, code and numbers. Postext sets the punctuation and the line breaks by the Japanese rules and adds a thin space where Japanese meets Latin.
What you'll build
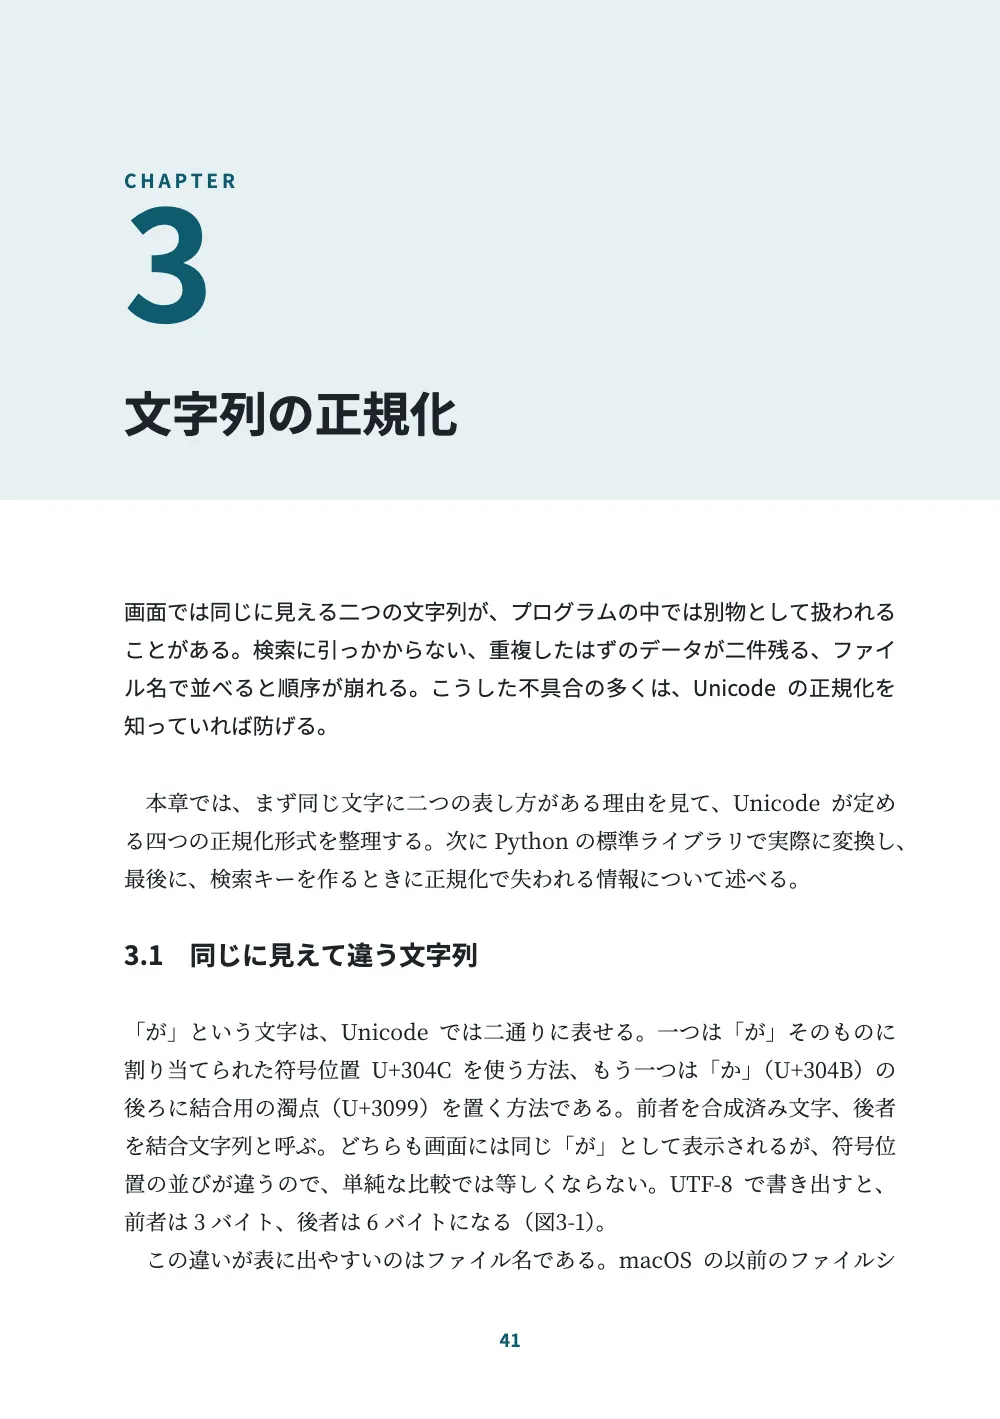
Five pages from chapter 3 of an invented Japanese programming book, 実践 日本語テキスト処理 (Practical Japanese Text Processing), on Unicode normalization. It is set as Japanese computer books are: A5, one column of 36 characters by 29 lines of Noto Serif JP at 9 pt, heads in Noto Sans JP, code in BIZ UDGothic. The text is the hard case for Japanese composition, because every other sentence holds a Latin word, a code point, a number or a function name: the line breaks follow JLReq’s strictest 禁則処理 (kinsoku shori), the punctuation keeps its full-width spacing, and a quarter em separates Japanese from Latin without anyone typing a space. A figure, a table, a code listing and page notes come with Japanese labels: 図3-1, 表3-1, superscript note numbers counted per page. Code listings and keycaps is the same kind of page in English.
This recipe answers
- How do I space Japanese punctuation: 、。「」 squeezed where they meet, a space after ?! and the bracket that opens a paragraph?
- Why may small kana, ー and closing brackets not start a line of Japanese, and how do I choose how strict the rule is?
- Why does my Japanese text come out with Chinese rules: 图 labels, small kana starting lines, kanji in Chinese forms?
The short answer
// locale 'ja' turns on JLReq composition: kinsoku at its strictest, full-width marks squeezed
// where two meet (」、 takes one em, not two), a closing mark keeps its half em at a line
// end, 、。 may hang past it, and a paragraph opening with 「 sets the bracket in the indent.
// The values below are the ones 'auto' picks for 'ja'; they are spelled out to be seen.
const cjk = {
  lineBreak: 'ja-very-strict', // no line starts with ー, small kana, 々, 」、。?・ or :
  punctuationWidth: 'fullwidth', // 、。「」 keep their em inside the line (JLReq §3.1.2)
  hangingPunctuation: 'allow', // 、。 hang only when the line would otherwise break before them
  paragraphStartBracket: 'half', // 「 at a paragraph start sits in the indent's second half
  latinSpacing: em(0.25), // 四分アキ between kana or kanji and Latin letters or digits
  grid: { enabled: true, charsPerLine: CHARS, linesPerPage: LINES }, // whole ems, whole lines
};
// The Latin is the Japanese face's own proportional Latin, at the text's size: never
// full-width A or a second face for the words in parentheses.
const bodyText = {
  fontFamily: MINCHO, fontSize: pt(BODY), lineHeight: pt(PITCH), color: col('ink'),
  boldColor: col('ink'), italicColor: col('ink'), referenceColor: col('ink'),
  textAlign: 'justify', firstLineIndent: em(1), indentAfterHeading: true, // 1 字下げ
  referenceBold: false, // 図3-1 and 表3-1 in the text weight: the face loads no bold
  hyphenation: { enabled: false }, avoidRunts: true, // no one-character last line
  // The grid cuts a list where the page ends: the four forms stay in one piece.
  shortListSplit: 'avoid', shortListMaxItems: 4,
};
Japanese rules from the tag, written out; the quarter-em Latin space
Ingredients
- Features
- Japanese punctuation spacing (yakumono)Japanese line breaking (kinsoku)Space between Chinese and LatinNotes in Japanese booksFootnotesLink addresses in printNumbered captionsFigure and Table in your languageNumbered headingsHeadings over body lines (gyōdori)Character gridChinese, Japanese and Korean fontsCode listingsCallout boxesTable styleCaption styleFigures and tables as resourcesRunning heads and foliosDesigned openersPDF export
- Also uses
- Citations in a citation styleChinese line breakingChinese punctuation widthsColumn balancingCross-referencesFigures exactly hereHeads by page roleParagraph stylesFonts embedded in the PDFCustom resource typesTables from data
- Type
- Noto Serif JP, Noto Sans JP, BIZ UDGothic (SIL OFL 1.1)
- Assets
- Figure 3-1, the bytes of が, drawn in code in the page’s palette (Postext Cookbook, CC BY 4.0)
Method
#1 · The Japanese rules come with the tag
The code is the short answer above. locale: 'ja' switches on the rules of JLReq, the W3C’s Requirements for Japanese Text Layout, and the values written out under cjk are the ones 'auto' picks for Japanese (East Asian typography). At ja-very-strict, no line starts with ー, a small kana, 々 or a closing mark, and no line ends with an opening bracket. The punctuation (約物, yakumono) keeps its full em inside the line, and two marks that meet, such as 」、, share one em. On page 41 the line that ends 実際に変換し、 sets its 、 past the right edge of the measure: that is ぶら下げ (burasage), and the engine uses it only when the line would otherwise have to push the mark to the next line. latinSpacing puts a quarter em (四分アキ, shibun aki) between Unicode and では, and between U+304C and を, though the Markdown has no space there. It goes next to a letter or a digit only: normalize() and is_normalized() end in a bracket, so the Markdown types a space between them and 関数.
The difference from Chinese is in the marks. A mainland Chinese book sets 、 and , at half width by default and 。 full (Kaiming); a Japanese one keeps every mark full width and squeezes only where two meet. Chinese line breaking has no small kana or ー to keep off a line start, so ja-very-strict is a level of its own.
#2 · Code in a monospaced face that has kana
// A ``` fence is set line by line as written, in codeStyle's face: the monospaced face,
// which has kana and kanji too, so a full-width character takes two half-width cells.
// The rest of the fence line (normalize.py) is the listing's title. Inline `code` is set
// in the same face, in the accent.
const codeStyle = {
  fontFamily: CODE, fontSize: pt(8), lineHeight: pt(12), color: col('ink'),
  background: col('tint'), snapToGrid: false, highlight: 'none', // one ink, as in print
  padding: { top: mm(2.5), right: mm(4), bottom: mm(3), left: mm(4) },
  marginTop: mm(2), marginBottom: mm(2),
  titleStyle: { fontFamily: CODE, fontSize: pt(7), fontWeight: 400, color: col('teal') },
  inline: { fontSize: pt(8.5), color: col('teal') },
};
The fence is a code block: Postext sets its lines as typed, in the face codeStyle names, in a tinted box under the title normalize.py from the fence line (code listings). highlight: 'none' keeps the listing in one ink, as the rest of the page, and codeStyle.inline sets each `name` in the same face, in teal. The face matters: the example’s string ガイド ABC ① needs half-width katakana, full-width letters and circled digits, which a Western code face lacks. BIZ UDGothic sets half-width Latin and full-width kana at fixed pitch, and a listing counts a full-width character as two cells, so the columns hold.
#3 · 図3-1 and 表3-1
const FORMS = `入力\tNFC\tNFD\tNFKC
が(U+304C)\tU+304C\tU+304B U+3099\tU+304C
ガ(U+FF76 U+FF9E)\tそのまま\tそのまま\tガ(U+30AC)
ABC(全角)\tそのまま\tそのまま\tABC
①\tそのまま\tそのまま\t1
㍻\tそのまま\tそのまま\t平成`;
const resources = [
  { id: 'tbl:forms', typeId: 'table', kind: 'table', createdAt: 0, updatedAt: 0,
    placement: { position: 'here' }, // at its ::resource line, under the paragraph citing it
    caption: '日本語の文字と四つの正規化形式(NFKDは、NFKCで合成された文字を分解した形になる)',
    table: { model: { ...parseTSV(FORMS), headerRowCount: 1, columnWidths: [34, 18, 26, 22] } } },
  { id: 'fig:bytes', typeId: 'figure', kind: 'svg', createdAt: 0, updatedAt: 0,
    caption: '「が」の二つの表し方。上段が符号位置、下段がUTF-8のバイト列',
    altText: 'が as one code point U+304C, three UTF-8 bytes E3 81 8C; and as U+304B and the '
      + 'combining voiced mark U+3099, six bytes E3 81 8B E3 82 99.',
    svg: { fileId: 'bytes.svg', width: 1175, height: 400 } },
];
defaultResourceTypes('ja') names the types 図 and 表 and numbers them by chapter with a hyphen, and continuation.headings makes this chapter 3, so the first figure is 図3-1. A ja document sets the label and the number solid and puts an ideographic space after the number, as Japanese books print 図3-1 「が」の二つの表し方, so the caption style only picks the face and the colours. The table is placed 'here', under the paragraph that cites it. The figure’s labels are Latin only, U+304C and E3 81 8C: the SVG names the code face in its style, and loadSvg embeds the font file before the picture is drawn.
#4 · Notes per page, the Japanese way
  footnotes: { fontSize: pt(7.5), lineHeight: pt(12), color: col('ink'),
    separator: { color: col('rule') } }, // at the column foot, 1 on each page, superscript
  // A link in a note prints its address after the text, in parentheses: the reader of the
  // printed book can type it. 'short' drops https:// and www.; the PDF keeps the full link.
  links: { print: 'inline', urlDisplay: 'short' },
The notes need no setting beyond their size: in a horizontal Japanese document the defaults are the ones JLReq describes for horizontal books, a note at the foot of the column where it is cited, numbered from 1 on each page, a superscript marker and a rule a third of the measure long (Footnotes). The marker goes before the full stop, 保存していた[^hfs]。, so the 。 never starts the next line apart from it.
Note 2 cites the Unicode report that defines the four forms, and the citation is a link: [Unicode Standard Annex #15「…」](https://www.unicode.org/reports/tr15/). A note cannot carry a note of its own, so a link inside one prints its address after the text, in parentheses; links.urlDisplay: 'short' drops https:// and www., and the PDF keeps the full link. links.print: 'inline' does the same for a link in the text (Links in print). The note opens with Japanese words, so its first line fills out before the long Latin title.
#5 · A three-line section head
const BAND = 74; // mm from the trim's top
const opener = { enabled: true, minHeight: pt(PITCH * 10), slot: { elements: [ // text: line 11
  { kind: 'box', id: 'band', reserve: false, style: { backgroundColor: col('tint') },
    placement: { anchor: { to: 'page', edge: 'top-left' },
      size: { width: 'fill', height: mm(BAND) } } },
  { kind: 'text', id: 'kicker', content: 'CHAPTER', fontFamily: GOTHIC, fontSize: pt(8),
    fontWeight: 700, letterSpacing: pt(1.6), color: col('teal'), align: 'left',
    placement: { anchor: { to: 'container', edge: 'top-left' }, offset: { y: mm(0) } } },
  { kind: 'text', id: 'number', content: '{numberDecimal}', fontFamily: GOTHIC, fontSize: pt(64),
    lineHeight: 1, fontWeight: 700, color: col('teal'), align: 'left',
    placement: { anchor: { to: '#kicker', edge: 'below' }, offset: { y: mm(1) } } },
  { kind: 'text', id: 'title', content: '{titleText}', fontFamily: GOTHIC,
    fontSize: pt(20), fontWeight: 700, color: col('ink'), align: 'left', overflow: 'wrap',
    placement: { anchor: { to: '#number', edge: 'below' }, offset: { y: mm(5) },
      size: { width: mm(MEASURE) } } },
] } };
The chapter opener is a design on the H1: a teal band, the chapter number at 64 pt from {numberDecimal} and the title. The section heads use lineSpan: 3, 行取り (gyōdori): each takes exactly three body lines, its text centred in them, so the text after it goes on in step with the grid. headings.balancing.enabled: false keeps the engine from adding lines above heads to even out a page.
The whole recipe
// ═══ Postext Cookbook · Nº 123 · A Japanese technical manual: kana, kanji and Latin ═══
// https://postext.dev/en/cookbook/japanese-technical-manual
// Code: MIT · Text: original (CC BY 4.0) · Pictures: drawn in code
// Fonts: Noto Serif JP, Noto Sans JP, BIZ UDGothic (SIL OFL 1.1) · Needs postext ≥ 1.65.0
import {
  buildDocument, withLoadedFonts, renderPageToCanvas, defaultResourceTypes, parseTSV,
  registerResourceImage, inlineSvgFonts,
} from 'https://esm.sh/postext';
import { renderToPdf, decompressWoff2 } from 'https://esm.sh/postext-pdf';

const LANG = 'en'; // @lang: the language of the frame; the chapter is Japanese in both
const RECIPE = 'japanese-technical-manual';

// ─── 1 · Design ─────────────────────────────────────────────────────────────
// #region palette: ink, one deep teal for numbers, rules and labels, a pale tint for code
const palette = {
  ink: '#1d2327', // text: a cool near-black
  teal: '#0e5a6e', // the one accent: chapter number, heads' numbers, labels, the point box
  tint: '#e7f0f2', // the opener band, the listing's ground
  rule: '#b9c6cc', // hairlines: table rules, the note rule
  muted: '#5b666d', // running heads, folios, colophon
  paper: '#ffffff',
};
const col = (id) => ({ hex: palette[id], model: 'hex', paletteId: id });
const colorPalette = Object.entries({ ...palette, 'main-color': palette.teal })
  .map(([id, hex]) => ({ id, name: id, value: { hex, model: 'hex' } }));
// #endregion
const [MINCHO, GOTHIC, CODE] = ['Noto Serif JP', 'Noto Sans JP', 'BIZ UDGothic'];
const [BODY, PITCH] = [9, 16]; // pt: 9 pt text on a 16 pt line, 1.78 × the size
const [CHARS, LINES] = [36, 29]; // the type area in characters: 36 to a line, 29 lines
const MEASURE = CHARS * BODY * 25.4 / 72; // mm: 114.3

// #region answer: Japanese rules from the tag, written out; the quarter-em Latin space
// locale 'ja' turns on JLReq composition: kinsoku at its strictest, full-width marks squeezed
// where two meet (」、 takes one em, not two), a closing mark keeps its half em at a line
// end, 、。 may hang past it, and a paragraph opening with 「 sets the bracket in the indent.
// The values below are the ones 'auto' picks for 'ja'; they are spelled out to be seen.
const cjk = {
  lineBreak: 'ja-very-strict', // no line starts with ー, small kana, 々, 」、。?・ or :
  punctuationWidth: 'fullwidth', // 、。「」 keep their em inside the line (JLReq §3.1.2)
  hangingPunctuation: 'allow', // 、。 hang only when the line would otherwise break before them
  paragraphStartBracket: 'half', // 「 at a paragraph start sits in the indent's second half
  latinSpacing: em(0.25), // 四分アキ between kana or kanji and Latin letters or digits
  grid: { enabled: true, charsPerLine: CHARS, linesPerPage: LINES }, // whole ems, whole lines
};
// The Latin is the Japanese face's own proportional Latin, at the text's size: never
// full-width A or a second face for the words in parentheses.
const bodyText = {
The composed script.js runs as it is: paste it into any page’s module script, or open the recipe on CodePen. Recipe folder on GitHub ↗ (opens in a new tab)
Variations
#Let small kana and ー start a line
ja-strict is JLReq’s rule for general books: っ, ゃ and ー may open a line, which gives the breaker more places to cut and fewer spread lines.
-  lineBreak: 'ja-very-strict', // no line starts with ー, small kana, 々, 」、。?・ or :
+ lineBreak: 'ja-strict', // small kana, ー and 々 may open a line#No space between Japanese and Latin
Some publishers set Latin words solid against the kana, with no quarter em.
-  latinSpacing: em(0.25), // 四分アキ between kana or kanji and Latin letters or digits
+ latinSpacing: em(0), // Unicodeでは, set solidPitfalls
Pitfall
Tag a Japanese text 'ja', never zh-Hans or LANG
A recipe's editions are en and es, but a Japanese sample is Japanese in both: `locale: LANG` would tag it English or Spanish, and a Chinese tag would set it by the Chinese rules (Kaiming punctuation, small kana free to start a line, 图 for 図, Chinese glyph forms in the PDF). From postext 1.30 the tag is also the language the text is shaped in (measured, painted and embedded), so any tag but 'ja' gives other glyph forms than the Japanese ones (the Chinese ones under a Chinese tag) and other line breaks. Write 'ja': it picks the Japan region (JLReq line breaking and punctuation, sesame emphasis marks, furigana spacing, 図 and 表 labels) and turns hyphenation off. The lint fails a text with kana under a zh or ko tag. Japanese line breaking (kinsoku) →
Pitfall
Set Japanese in a Japanese face
Noto Serif SC and TC have kana, but they draw the kanji in Chinese forms (直, 骨 and 角 differ) and the kana in a Chinese design. Set the text in Noto Serif JP or Shippori Mincho B1 and the heads in Noto Sans JP, loaded with loadCjkFonts. Fontsource's Japanese files hold no hentaigana or other historic kana (U+1B000–1B16F): loadCjkFonts fails on them and the PDF prints boxes, so write the modern kana or ship a face that has them in the recipe's assets. Shippori Mincho also lacks the macron vowels ō and ū: set rōmaji in a Latin face. Kana, kanji and rōmaji →
Pitfall
Chinese faces load by slices, through the cjk block
Fontsource serves a Chinese, Japanese or Korean family as about a hundred files per weight, each covering a range of characters. loadFonts fetches only the latin file, so on screen the Han characters come from a system face and measure wrong, and fontsourceProvider hands the PDF that latin file, which prints them as empty boxes. List the cjk kit block, call loadCjkFonts(FONTS, markdown) after loadFonts (once per voice, with the text it sets, when the book uses several CJK faces) and give renderToPdf fontProvider: cjkPdfProvider: both take the files that hold the text's characters. Chinese, Japanese and Korean fonts →
- A Latin word cannot be broken inside a Japanese line, so a long one at the end of a line leaves the line before it spread between its characters. The first draft of this chapter glossed its terms in English, 正準等価(canonical equivalence), and two lines came out loose; the English terms were dropped where they did not help the reader.
- Choose the code face by the characters the code holds. M PLUS 1 Code, the first face tried here, has no half-width katakana: the screen fell back to a system face for ガイド and the PDF lacked the glyphs.
- A listing splits between its lines across pages, with at least two lines on each side (
codeStyle.splitMinLines). On page 43 the room left under 3.3 is too shallow for the title and two lines, so the whole listing opens page 44;keepTogether: truekeeps every listing in one piece. - On a character grid a page takes its 29 lines whatever a paragraph or a list does at the turn, so the list of the four forms would leave its first item, NFC, alone at the foot of page 42.
shortListSplit: 'avoid'withshortListMaxItems: 4moves the whole list to page 43, and page 42 ends a line short above its notes.
Credits
- Recipe
- Ignacio Ferro
- Text
- Original prose, CC BY 4.0
- Images
- Figure 3-1, the bytes of が, drawn in code in the page’s palette · Postext Cookbook · CC BY 4.0
- Fonts
- Noto Serif JP (SIL OFL 1.1) · Noto Sans JP (SIL OFL 1.1) · BIZ UDGothic (SIL OFL 1.1)
Edit this write-up ↗ (opens in a new tab)Recipe folder on GitHub ↗ (opens in a new tab)